Written for: For developers
Semantic layer entity model
Semantic Layer Document V3 is the authoring model used by the editor, its Dev tab, revisions, and MCP changes. It separates physical data structure from reusable business meaning while keeping every reference explicit.
Use Author a semantic layer over MCP for task-oriented MCP guidance. This page explains what the model contains and how its parts relate.
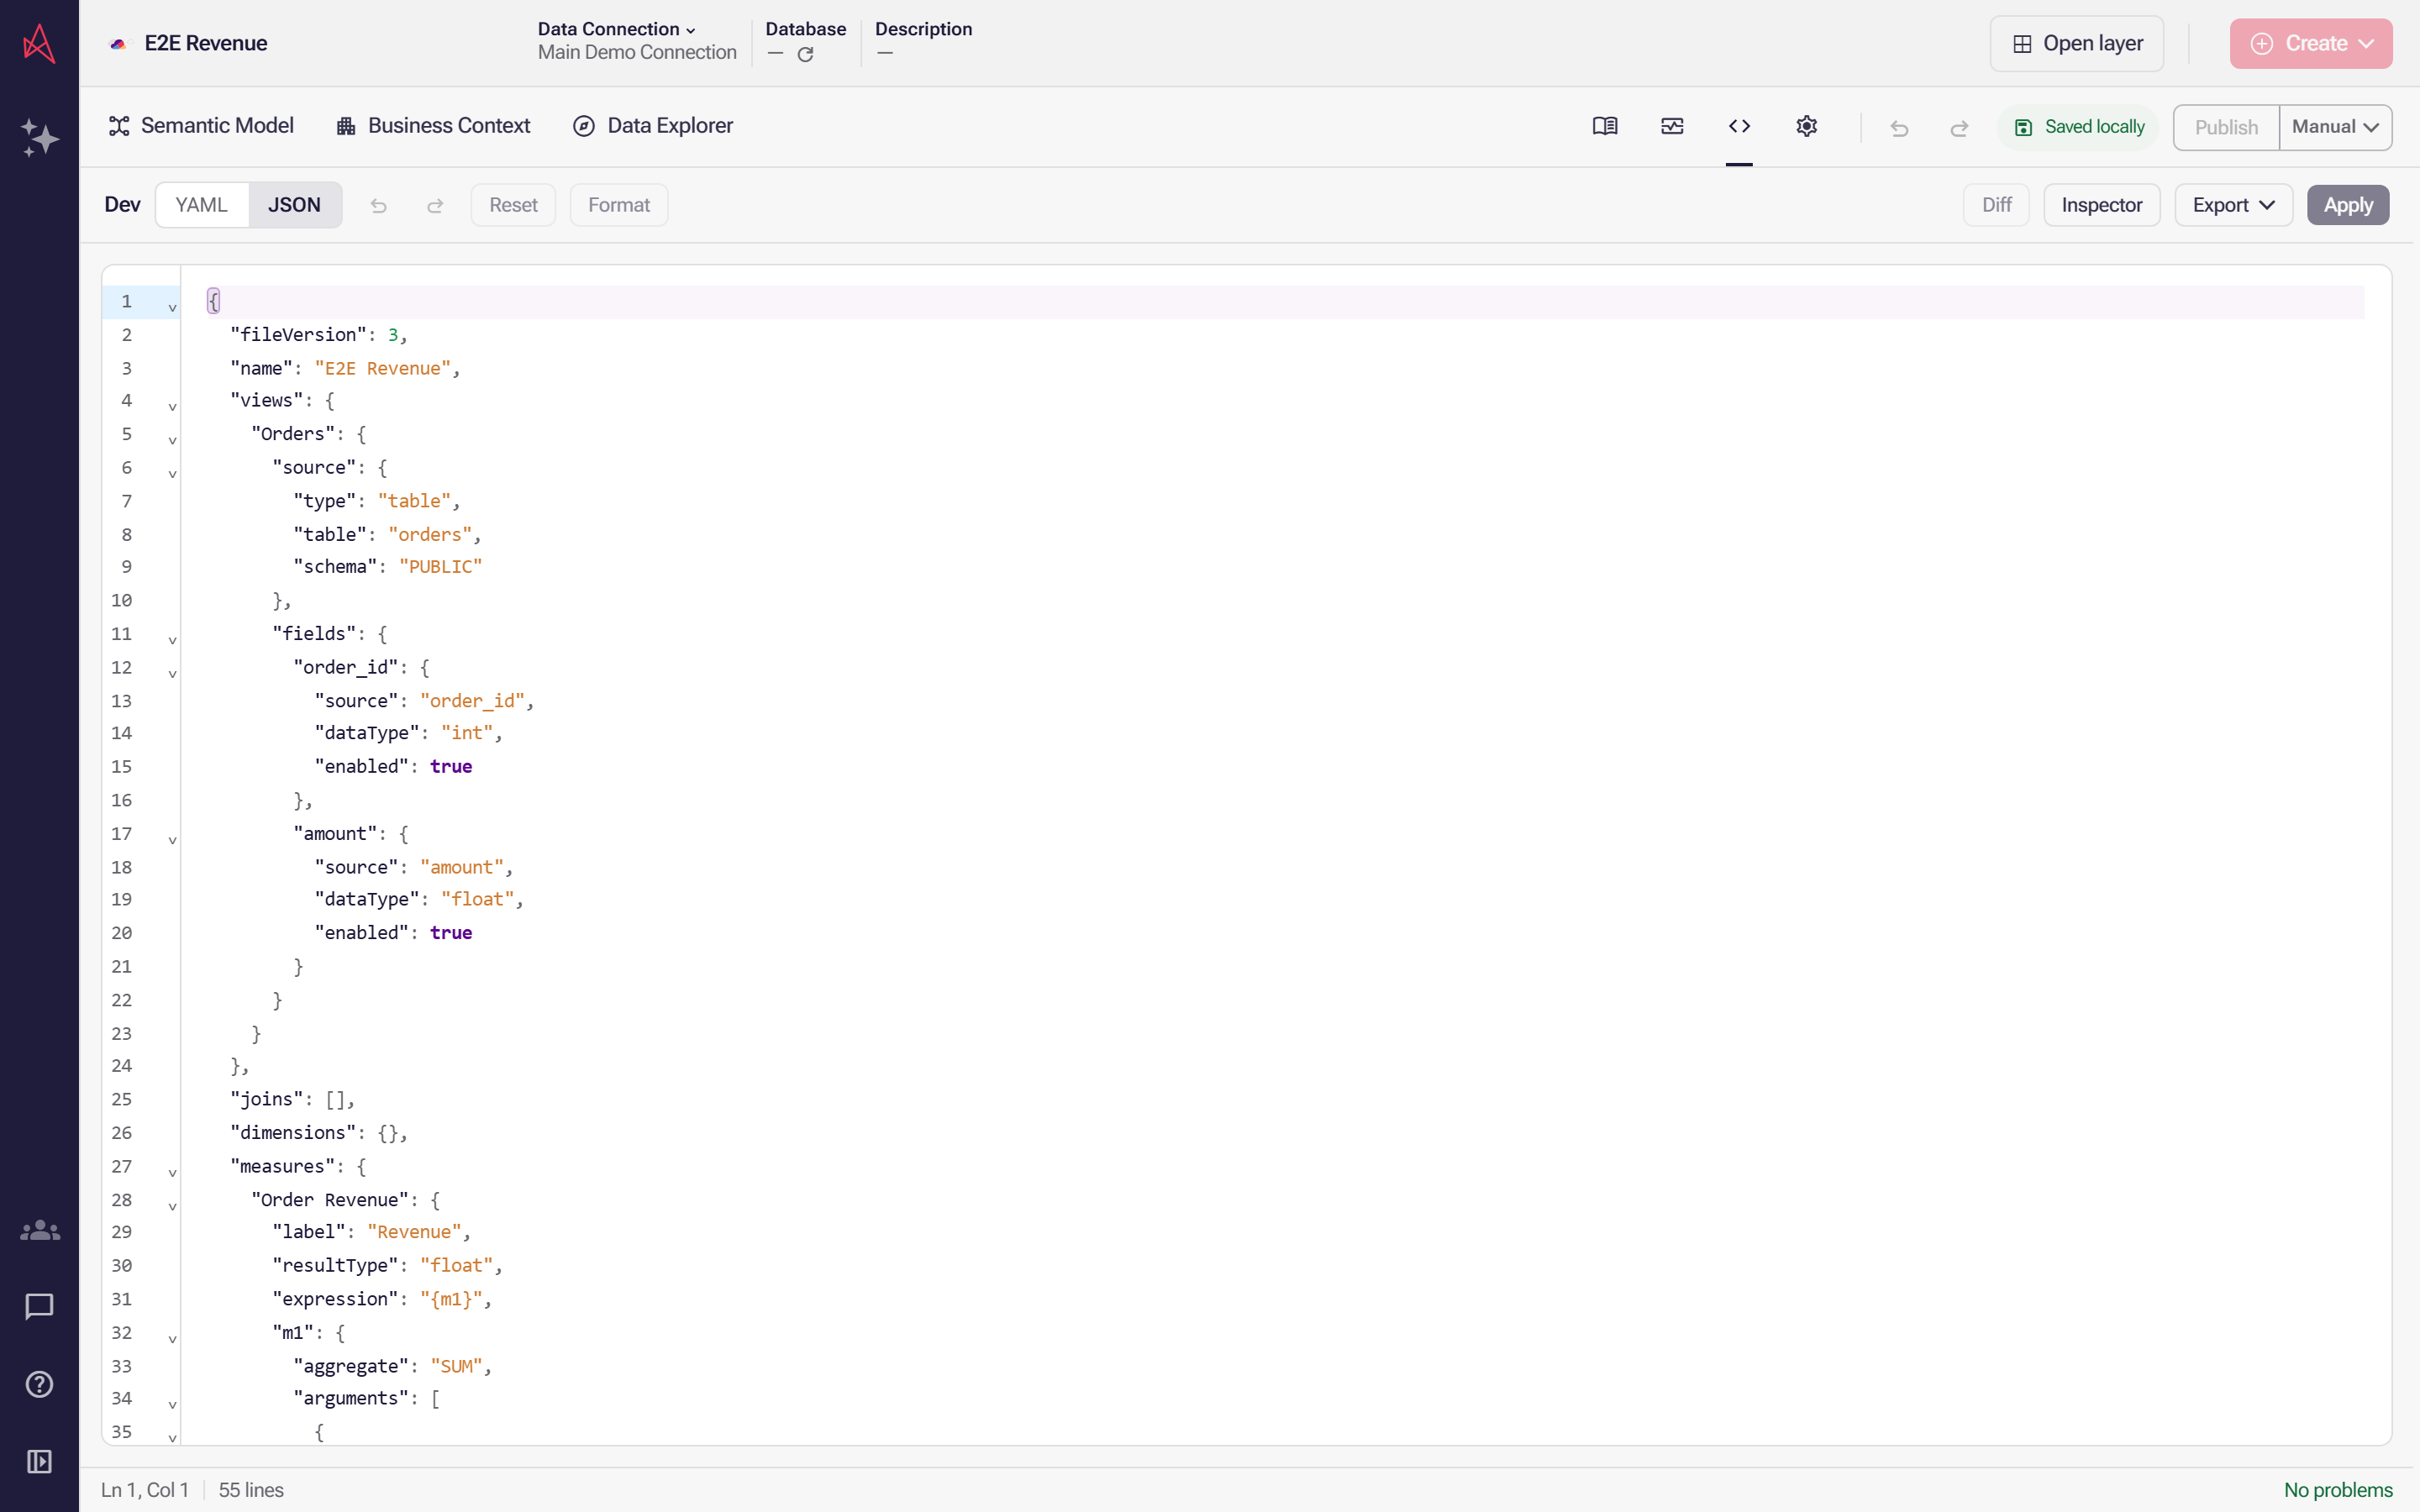
Developer View holds the whole layer as one JSON document; with the text untouched, Reset, Format, Diff and Apply stay inert. Change this measure's display label to begin.
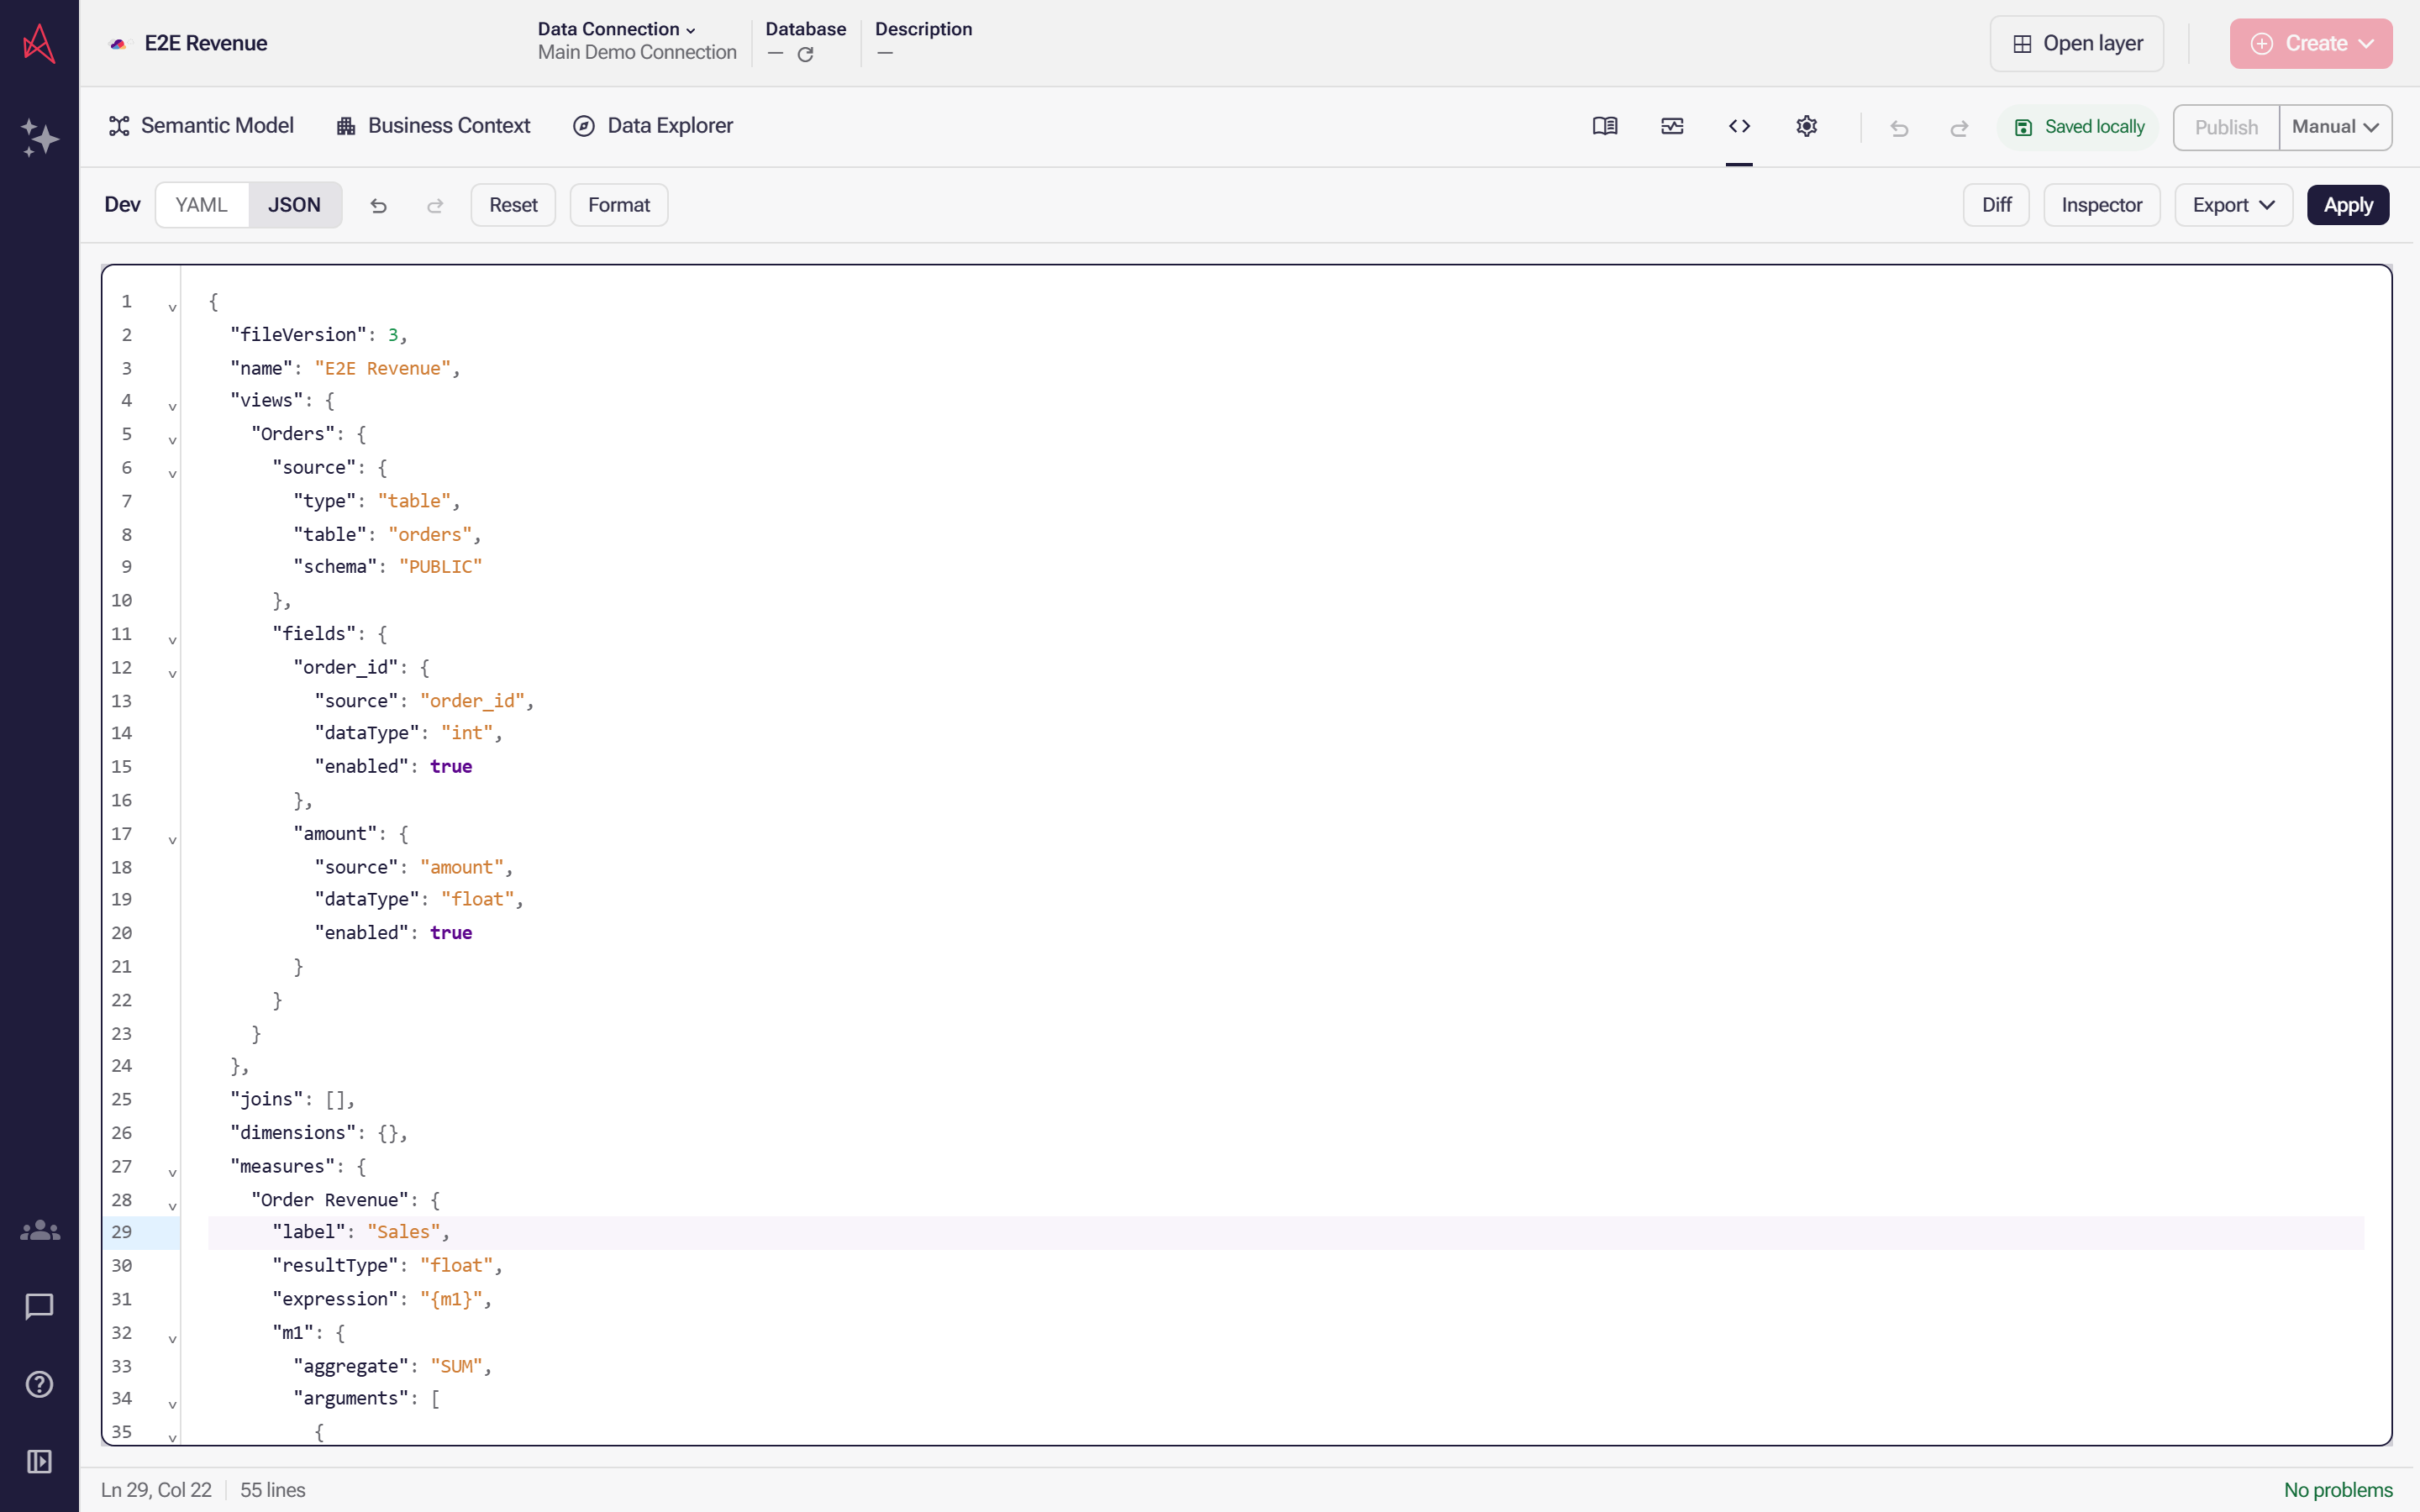
Changing this measure's display label leaves the edit pending in the text and turns on Reset, Format, Diff and Apply; open Diff to see what will change.
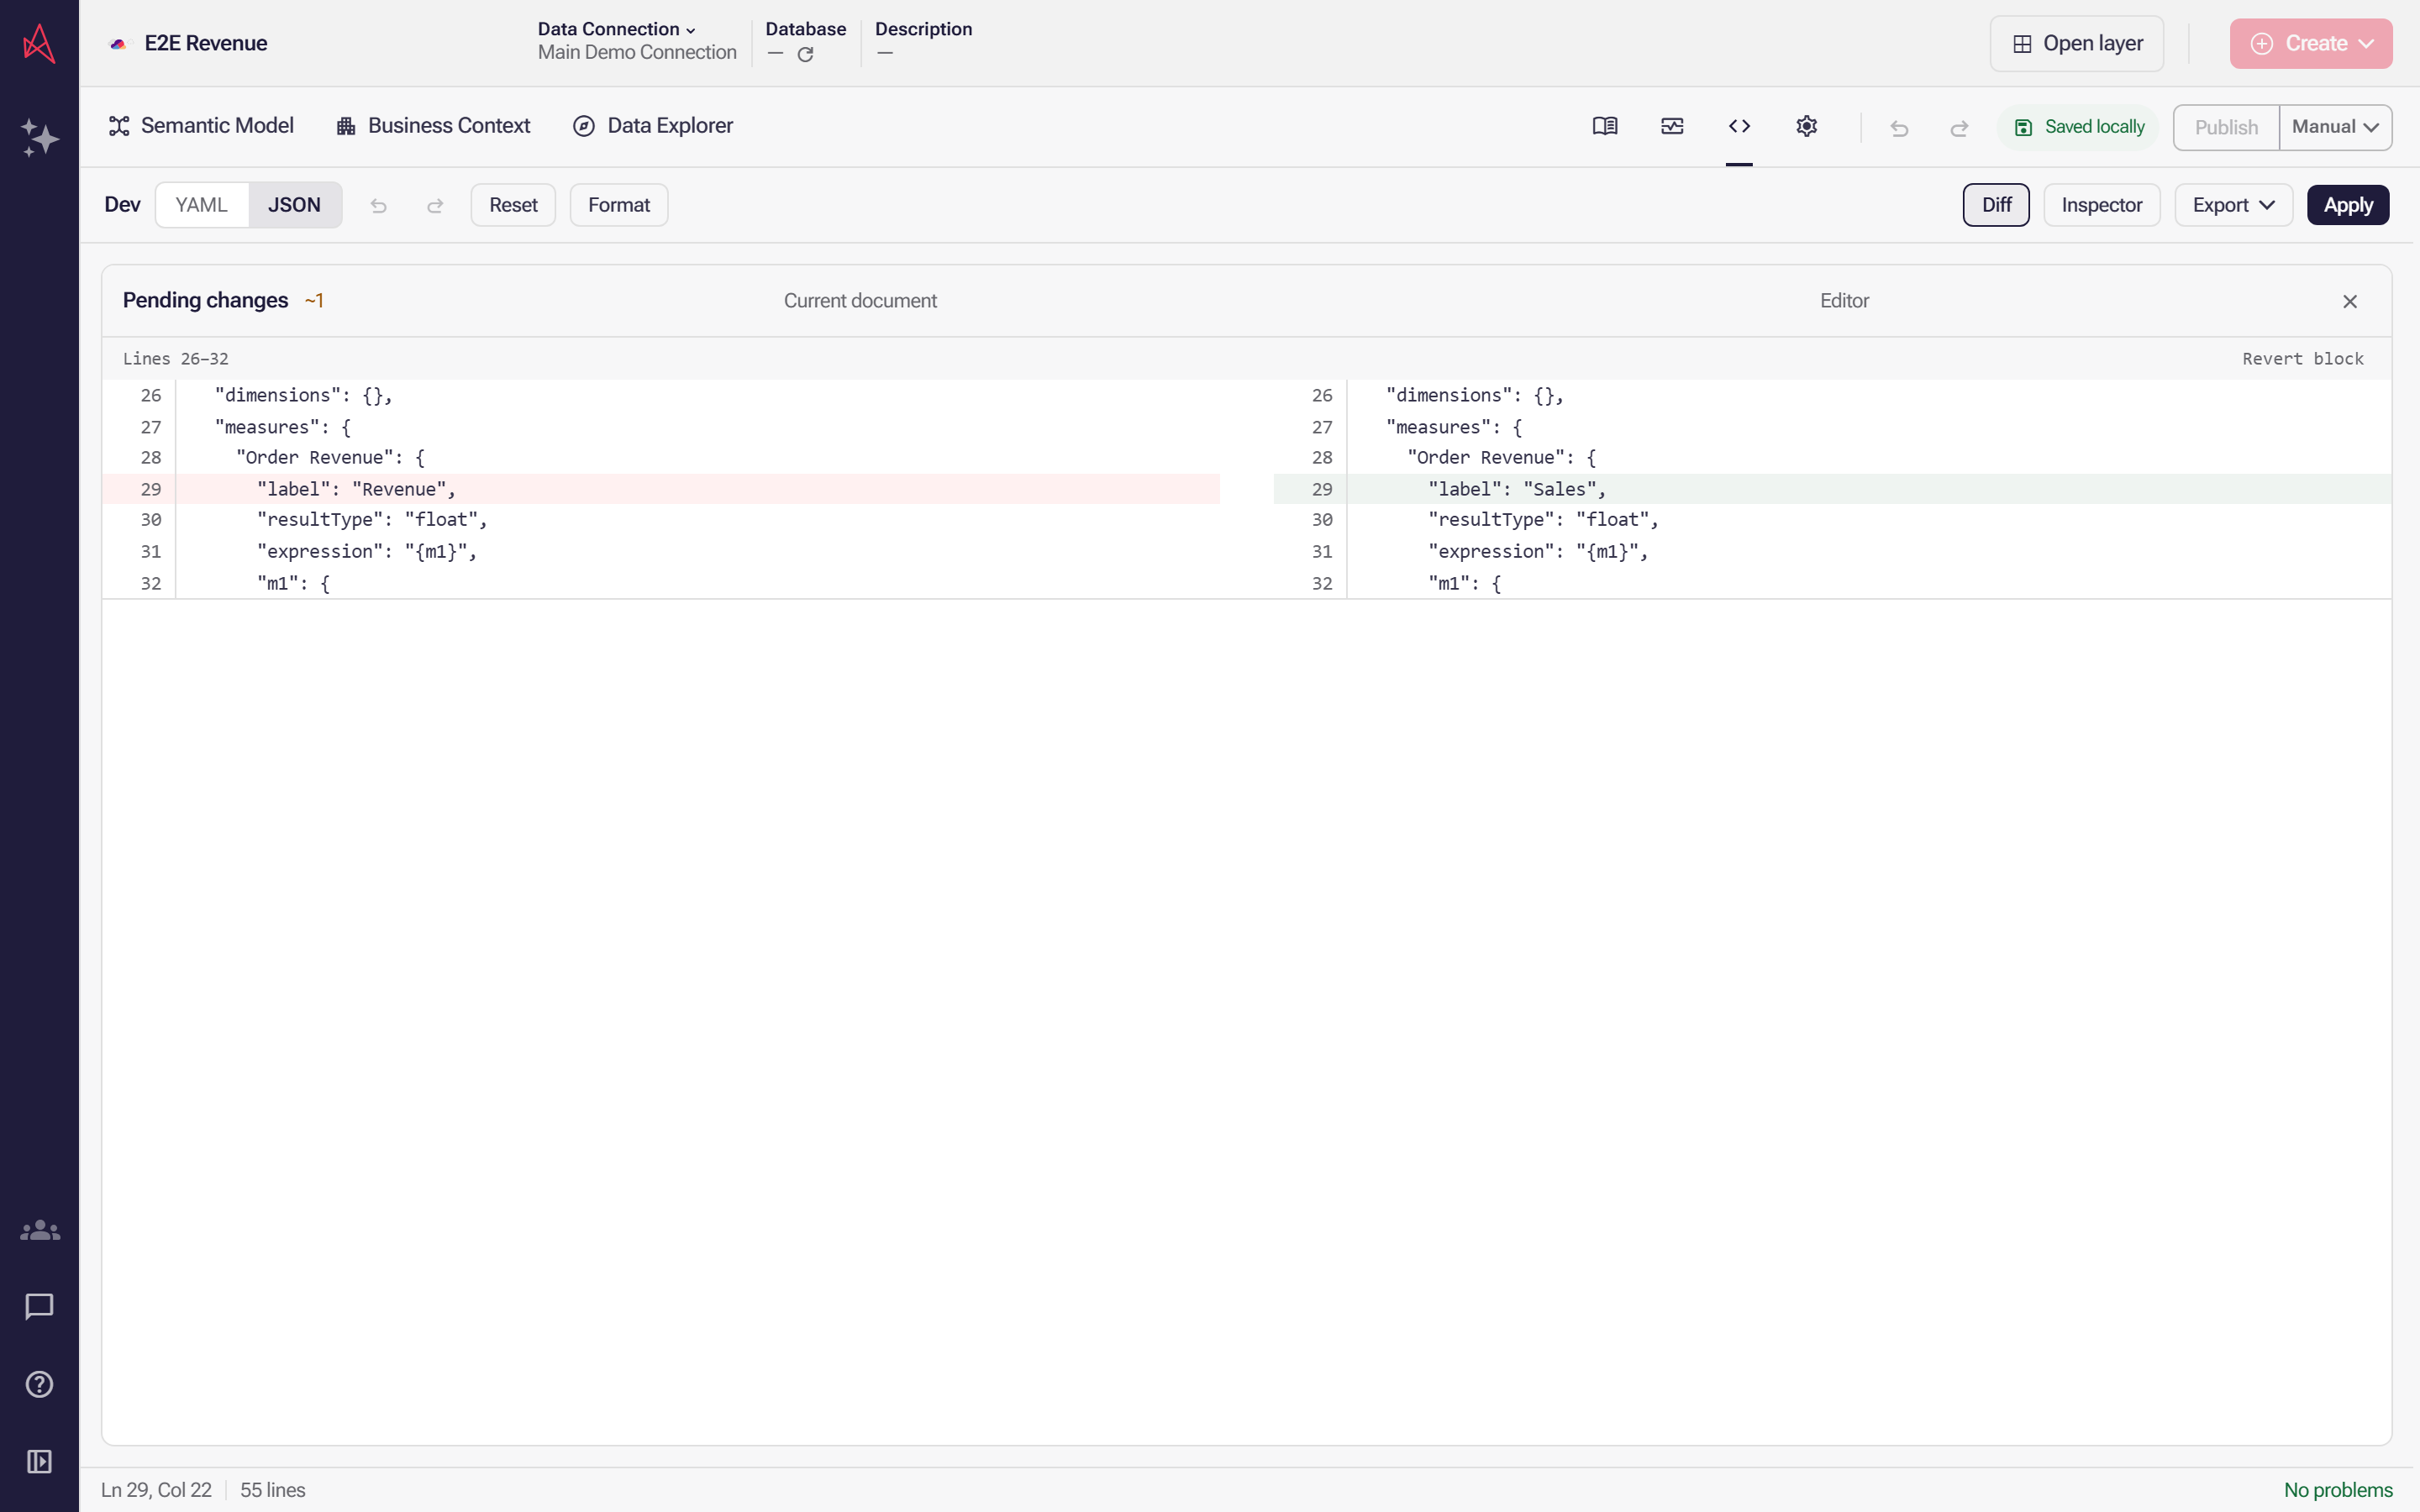
Diff sets the current document beside your text, counts the lines that change, and offers Revert block to put a changed block back; Apply writes your text to the model.
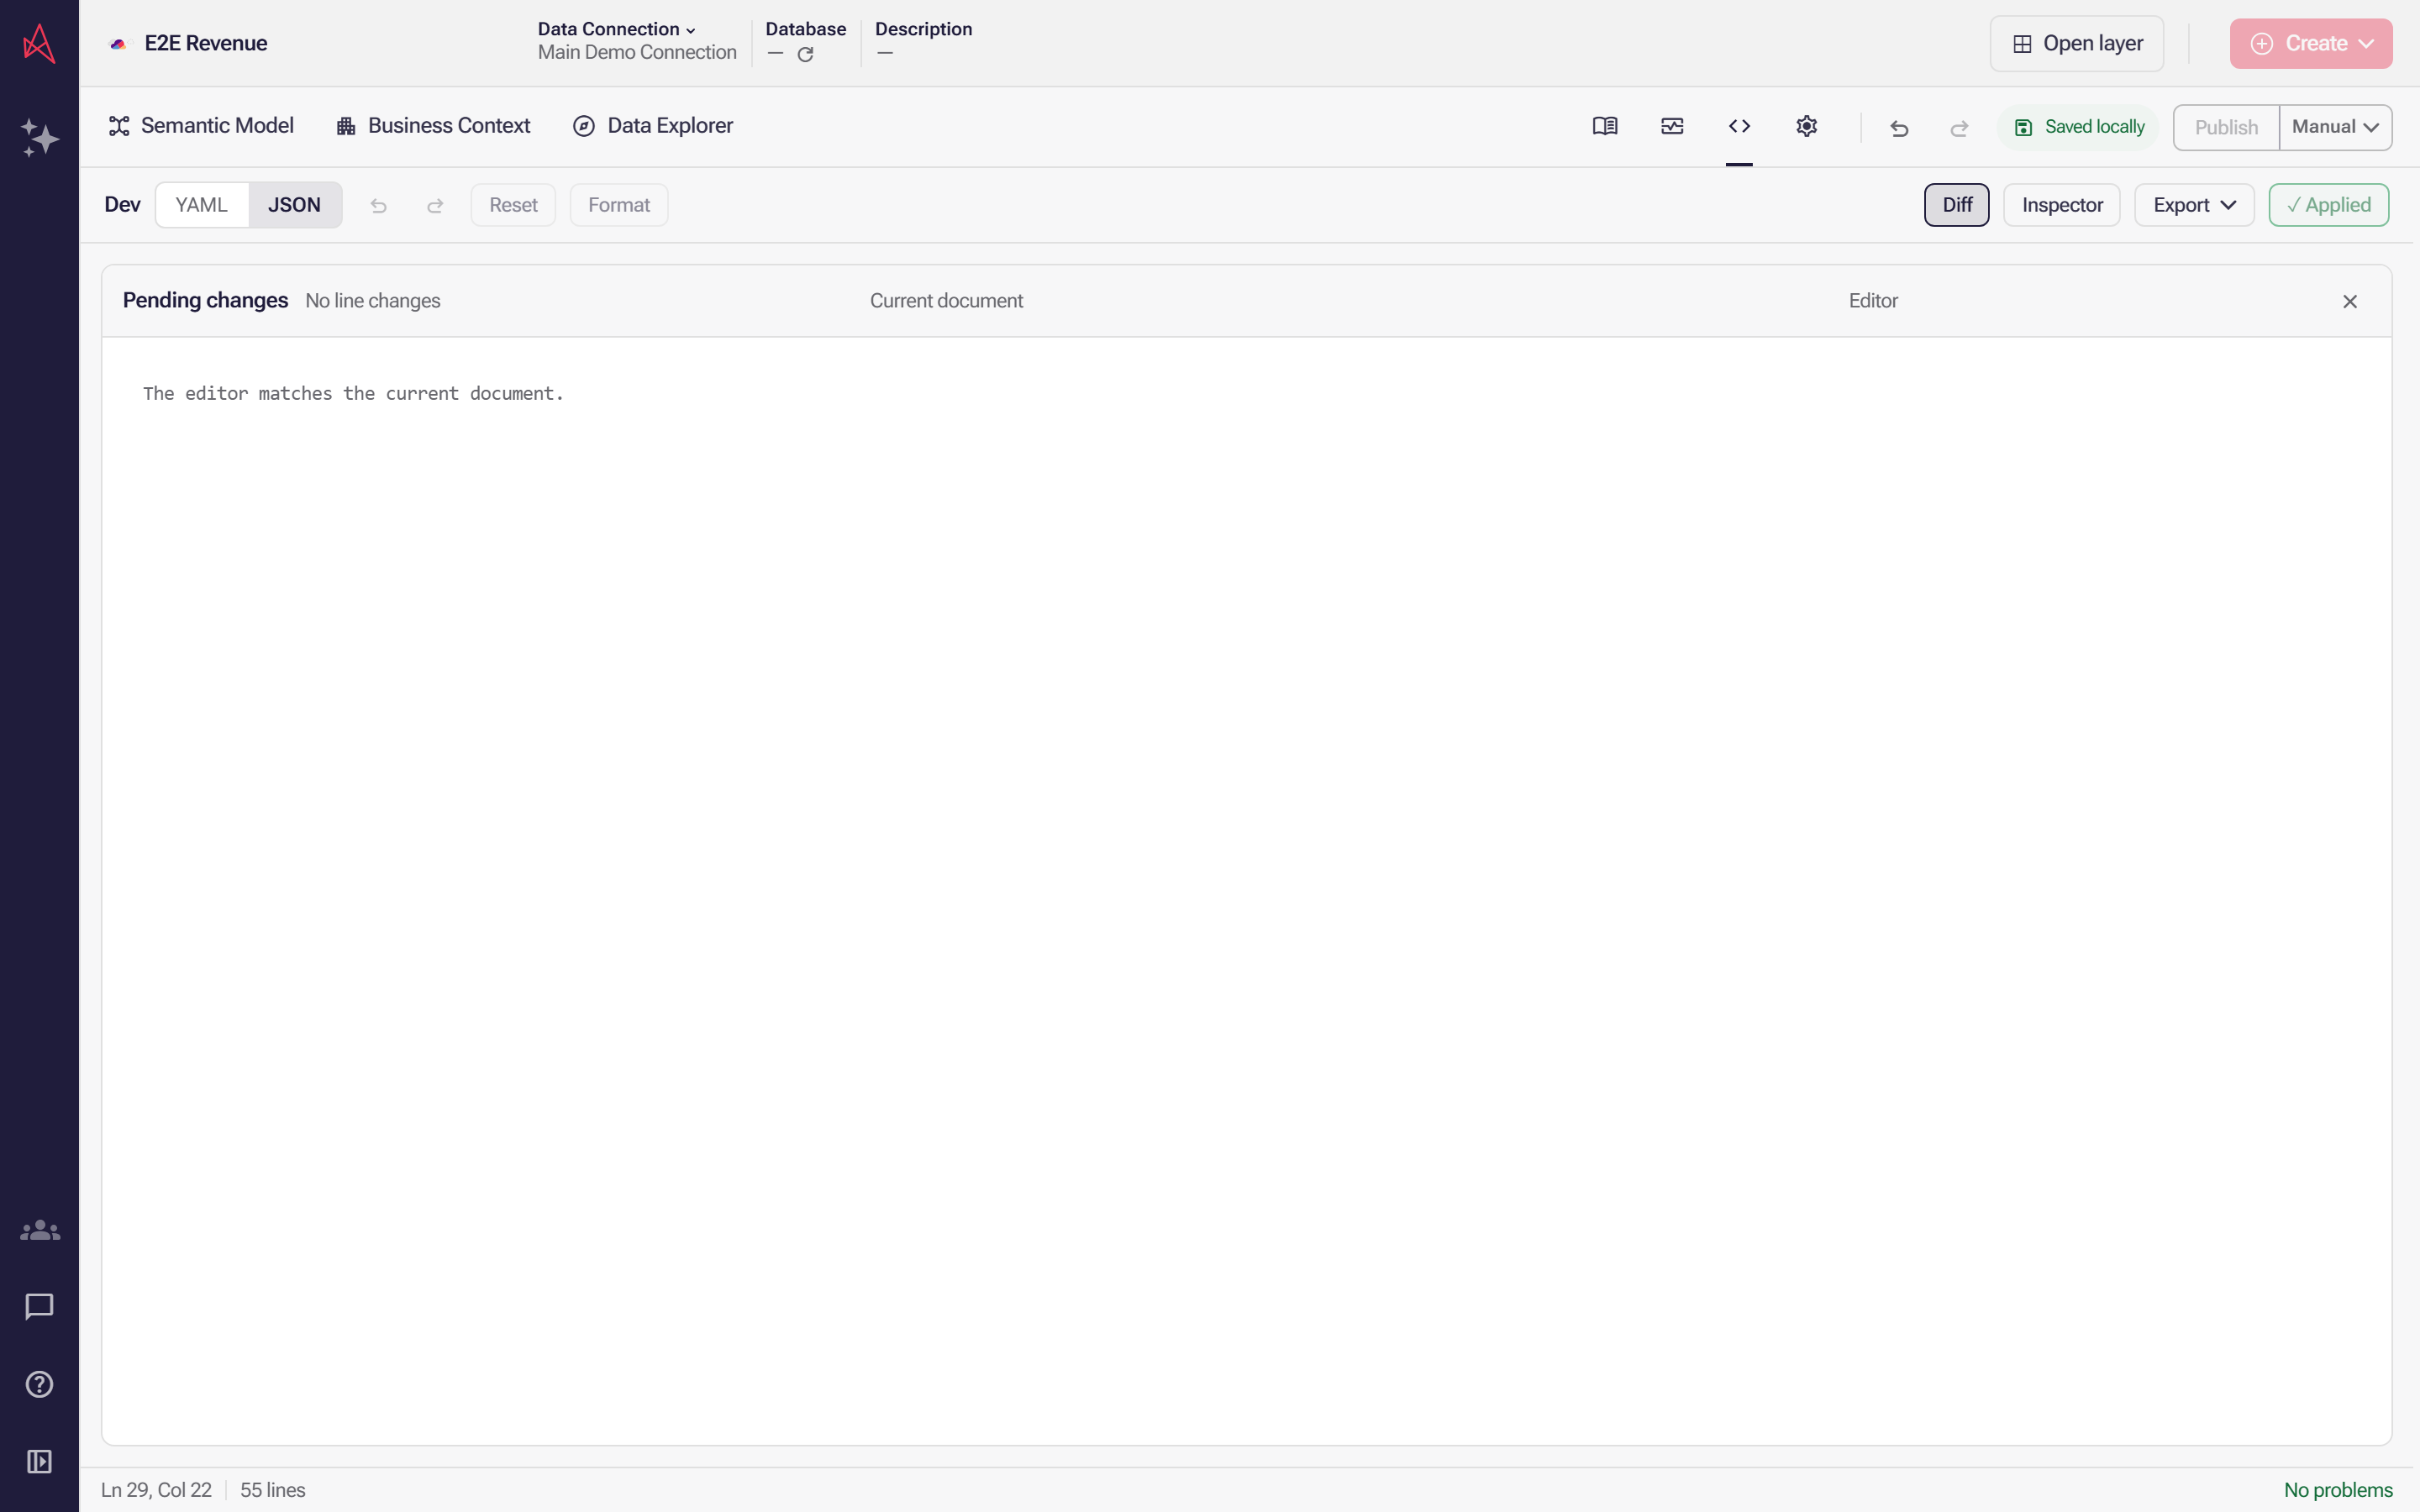
Apply replaces the model with the text you wrote: the button reads Applied, then goes inert, and the diff reports no line changes. Check the result under Business Context.
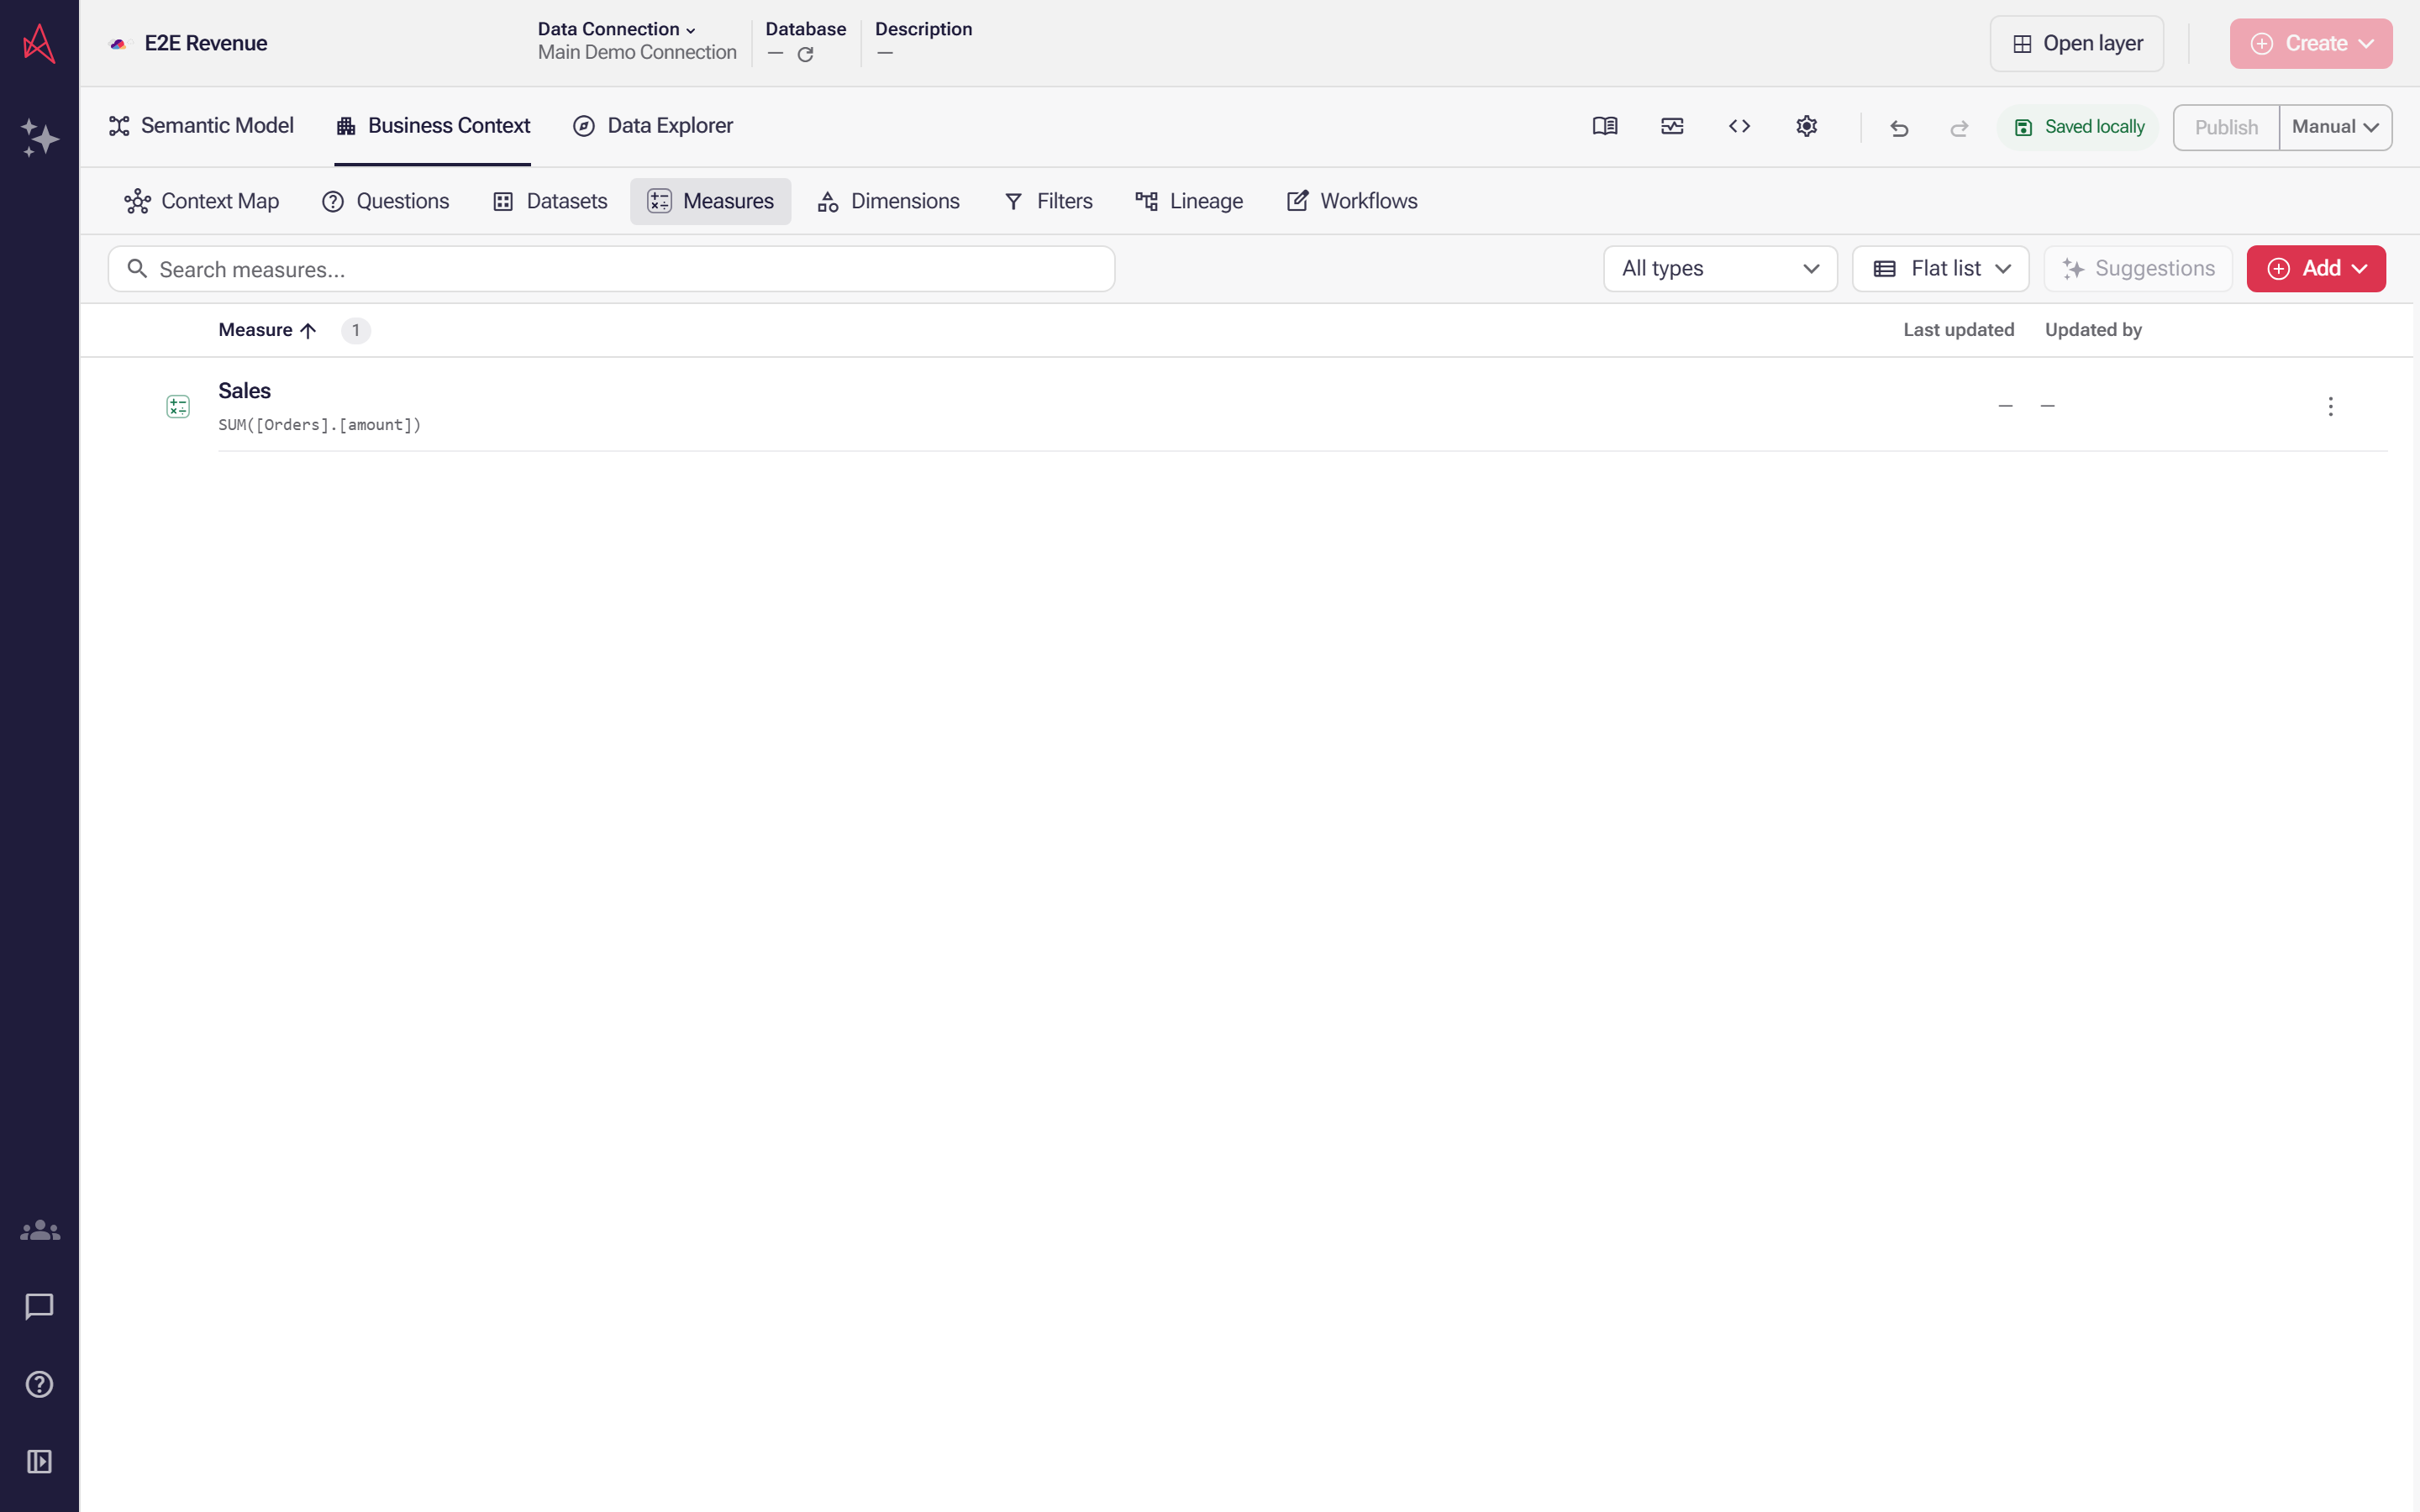
Measures lists the measure under the display label you typed as text, so the edit reached the ordinary editor; open the row to see both halves.
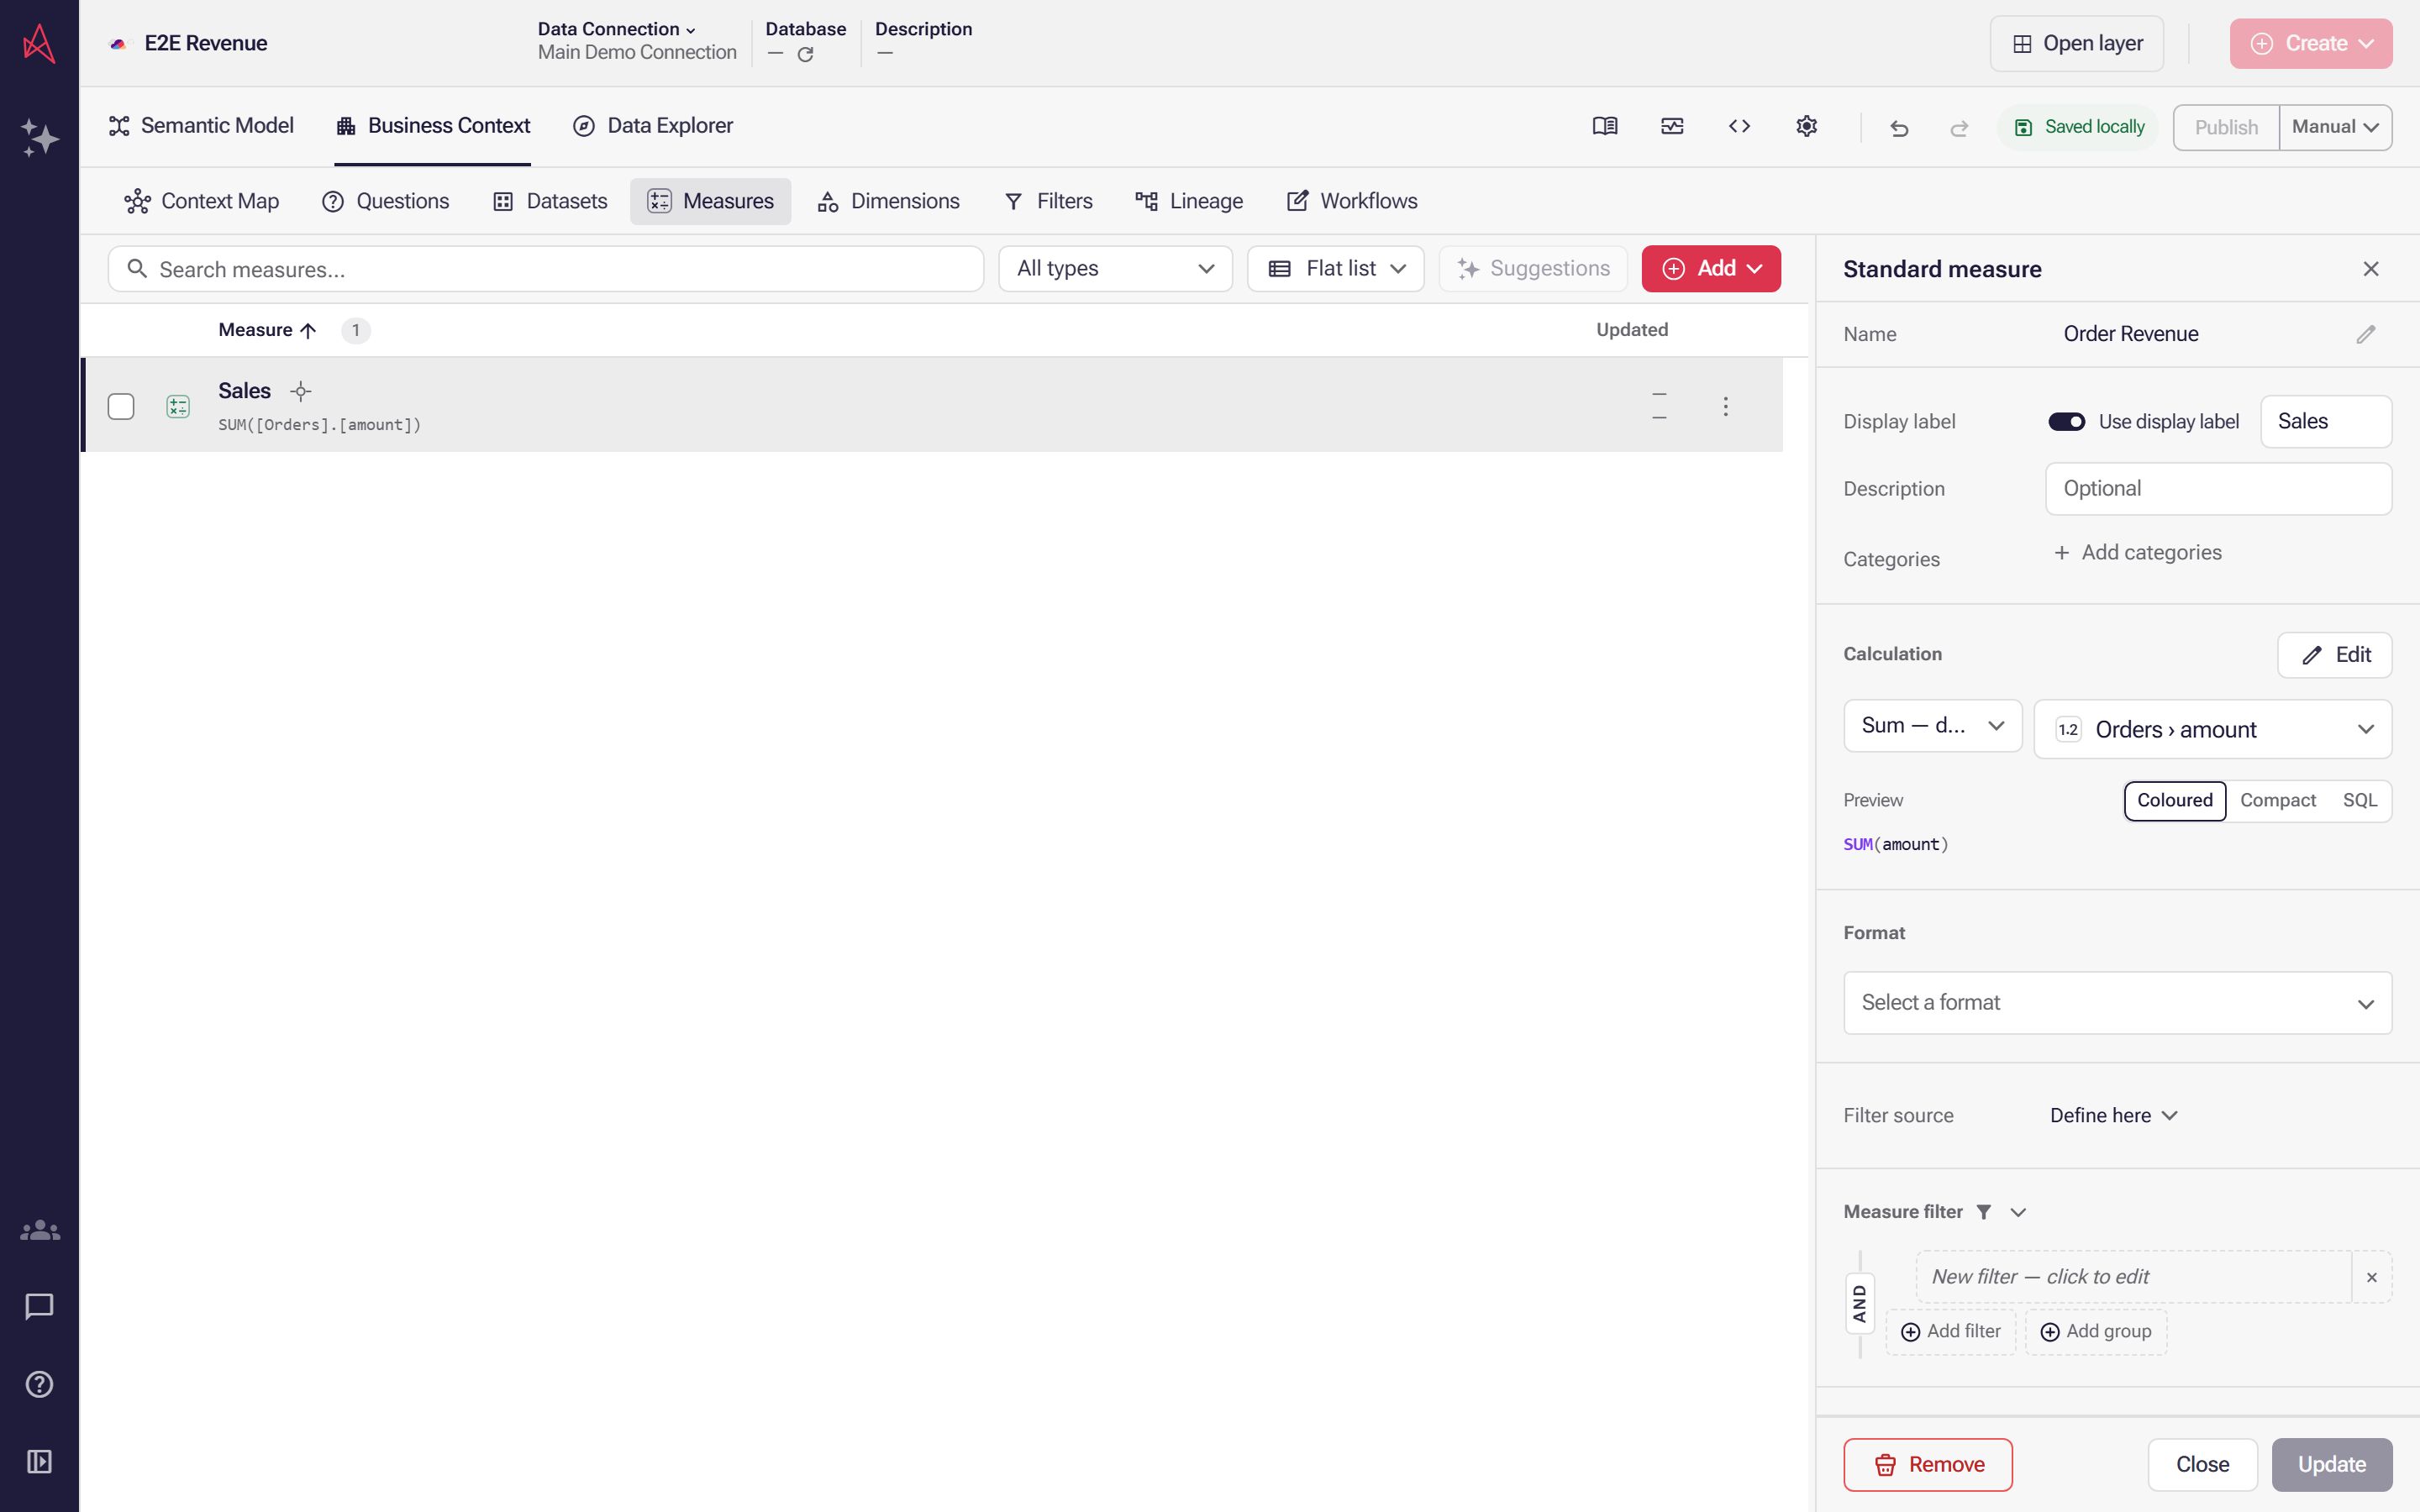
Opening the measure shows both halves of what you edited: the label controls its display text, while Name stays the key other entities reference.
Document version
Section titled “Document version”New documents and exports use fileVersion: 3. V2 documents remain readable: loading migrates their supported calculations and result-filter references to canonical V3; subsequent saves write V3. This is not a promise that older editors can read V3. Keep older clients from rewriting migrated documents. See migration and compatibility for ambiguous-filter handling and retained history. The document version is independent of the MCP tool contract.
Named filters live in root filters. Each defines either filters or associativeFilters, with no type. A consumer uses reference: { filter: name } in its regular or associative filter slot. Invalid references remain visible as document errors; selectors prevent incompatible choices.
Business questions have a complete YAML reference.
Draft data-actions contract
Section titled “Draft data-actions contract”The optional dataActions collection is a feature-gated Private Preview draft contract, marked in its schema and documentation. New or changed definitions require the data-actions feature flag; existing definitions remain readable and removable when it is disabled.
While this contract remains draft and feature-gated, breaking changes are allowed without automatic migrations. Affected definitions may need manual repair or recreation. This exception applies to data actions; the rest of the V3 document retains its documented compatibility rules. Saving or publishing a layer does not stabilize this contract. No draft-version field is added to saved documents.
Current definitions register a mapped table source’s writable operations and fields, or an existing stored procedure’s ordered warehouse arguments. Registration metadata is editor-owned. Data Actions have no separate access mode or user/group ACL. SQL or procedure code must enforce business access using trusted caller context; a view’s read filter does not automatically restrict writes. Table actions cannot target inline or custom-SQL views. Procedure schema, name, parameter names and warehouse type text must contain a nonwhitespace character; meaningful native identifier spacing is preserved.
Earlier draft definitions containing access are rejected. Remove that property and put the business authorization in the implementation; no automatic migration is provided. Discovery and status lookup are unavailable. Authoring, validation and preparation do not execute warehouse mutations, and publishing does not execute a definition. A published action runs through the Private Preview astrato_semantic_layer_run_data_action tool or from a published App.
Table-action references participate in field rename analysis and lineage. Writable tables and virtual procedures show authored field, dimension and measure context, plus mapped reads, writes and row-count checks derived from virtual-procedure SQL. A native stored-procedure workflow links only to its warehouse procedure through Calls; its body effects remain unknown, and parameter context adds no table or field edges. Workflow and warehouse-procedure nodes follow the data-actions feature flag. Missing references remain diagnostics, and the current usage catalog does not report workflow usage.
When the feature is enabled, Business Context → Business Workflows lists the registrations after Lineage. Search by name, description, category or target, or filter by kind or category. Group by category files each workflow under every category it carries, with those that have none last; Flat list is the default. Select a workflow to inspect its saved properties and version history. Create and edit writable-table registrations in this tab, or use Developer View or an imported document. Table registrations reference tables already included in the semantic map. The table picker offers mapped warehouse tables; an invalid saved target remains visible so you can repair it. Uncommitted name or description input prevents collaboration updates from replacing local work. The property panel has collapsible definition, table, operations and fields sections. Select a native stored procedure from the connection catalog to register its target and ordered signature. Selecting it again refreshes the signature; the catalog supplies native types. Business access belongs to the SQL or procedure implementation.
Stored workflow diagnostics remain available in Issues while the feature is disabled, including warnings that do not block publication. Open the issue link to inspect the definition in the Dev tab or remove the registration. Adding or changing a workflow still requires the feature flag.
Procedure catalog reads are limited to 2,000 entries. A larger result fails explicitly instead
of returning an incomplete list; select a narrower schema before checking registrations. Catalog
reads do not execute the stored procedures. Catalog signatures preserve nested native types and quoted argument names, including PostgreSQL array and user-defined types and Databricks precision and nested definitions. Malformed responses fail as unavailable catalogs. Unnamed inputs use a positional $1, $2, … label; Redshift uses these labels for every input because its catalog view reports ordered types without parameter names. Redshift signatures at the catalog’s 512-byte limit are rejected as potentially incomplete.
The procedure picker groups entries by schema and shows their parameter types. You can open and search it while metadata loads. Reload refreshes procedures and schema or dataset choices, including newly created or granted schemas. BigQuery requires a dataset selection before loading procedures. Other connections can browse all schemas or select one schema, including when the whole catalog exceeds the limit. Procedures with multiple signatures for the same native schema and name cannot be registered by name.
Publishing checks each registered procedure against the current catalog, including its exact schema and name, ordered parameters and return type. A missing, ambiguous, changed or unavailable signature blocks publication. Catalog checks are snapshots and do not prevent later warehouse changes.
In Private Preview, the optional writeback.mode setting selects dataSource or dataActions. When the feature is
enabled, Settings → Business Workflows offers Business Workflows or Data connection permissions (marked Legacy). Each selection saves an explicit mode. An absent setting means dataSource, preserving connection-governed writes. Both modes are saved authoring and preparation metadata. Existing explicit table-write and procedure APIs remain governed by their own permissions and do not execute these definitions. This setting is also draft and requires the
data-actions feature flag when changed or imported, including version restores.
New layers and imports use dataActions when the feature is enabled. Opening an existing layer
does not select a new mode, even if its model is empty. Copies retain their source mode, including
an absent setting.
With MCP tool contract 6.66.0 or later and the data-actions feature flag enabled (Private Preview), use
astrato_semantic_layer_set_writeback_mode with a layer ID and mode: dataSource or
mode: dataActions. It requires sl:write, stores either choice explicitly in the draft, and
publishes nothing. Integrated authorization also requires permission to edit the layer. Nash uses the same tool. The tool is omitted from discovery and refused at
invocation while the flag is disabled.
Writable fields have two scopes: All fields or an explicit selection. Clearing the selection permits no writable fields. Changing tables or cascading a field deletion preserves an empty restriction instead of changing it to all fields. Cascading a table deletion removes the registrations that target it; keeping broken references retains them for repair.
In Private Preview, MCP and Nash author registrations with astrato_semantic_layer_list_data_actions, astrato_semantic_layer_get_data_action, astrato_semantic_layer_prepare_data_action_change and astrato_semantic_layer_apply_data_action_change. Prepare returns a target and current revision; apply atomically creates, replaces, updates, renames or deletes a registration. Native schema/procedure spellings must match the catalog exactly, and BigQuery needs a selected dataset. These tools execute no warehouse mutation. The workflow-policy tool also accepts an optional expected revision and changes registration admission without adding action ACLs.
Version compare lists action changes under Business Workflows and shows their operations, fields,
procedure signature and key-field scope. When the feature is disabled, existing actions remain
inspectable, but restoring an action addition or modification is unavailable. Removing an action
and restoring unrelated changes remain available. Importing edits from the earlier engine format
preserves the registered actions and writeback.mode.
Data action properties
Section titled “Data action properties”dataActions is an optional top-level map keyed by workflow name, each key holding at least one
non-blank character. Its sibling writeback holds only mode, either dataSource or
dataActions.
A workflow requires kind and implementation, and may carry description, categories, parameters,
fields and returns. categories is an optional list of free-text labels, each used once; the editor’s
Categories field and the MCP categories argument set the same property. kind is table, storedProcedure or virtualProcedure — the Add
menu’s Writable table, Stored procedure and Virtual procedure. Writable table is
offered disabled, with the reason Add a table to the layer first, on a layer with no mapped
table.
implementation has ten optional properties and no required one, so {} is well-shaped:
| Property | Holds |
|---|---|
view |
The target table, on a writable table |
operation |
insert, update or delete — Insert rows, Update rows, Delete rows |
keys |
The Key fields binding map, keyed by field name |
values |
The Writable fields binding map |
bindings |
The virtual procedure’s binding map; a non-empty one is refused elsewhere |
dialects |
At least one dialect entry, keyed by dialect name |
expectRows |
Accepted and stored, and read by nothing |
transaction |
A boolean; absent means transactional |
batch |
One required mode, perItem or set; stored, and read by nothing |
result |
What the workflow returns |
dialects is keyed by one of exactly thirteen names — snowflake, dremio, postgres,
supabase, redshift, google_bigquery, databricks, clickhouse, trino, athena, duckdb,
gsheet-duckdb, gsheet — and an unknown key is refused as unknown authored SQL dialect. Each
entry holds exactly one of procedure or statements, plus optional database, schema,
arguments and result; both or neither is refused as expected exactly one procedure or statements. A statement requires name and sql and may carry a non-negative expectRows, which
is the editor’s Expected rows — left out entirely rather than set to zero when no count is
wanted. Instead of a fixed count, a statement may carry expectRowsFromList, the name of a list
parameter or binding: the step expects one row per distinct non-null item in that list on each run.
A statement sets one of the two, and a name that is not a list is refused.
transaction defaults to all-or-nothing. An absent property reads back as the editor’s
All or nothing; only an explicit false reads as Statement by statement. The checkbox is
All statements commit or none.
A result requires mode — rows, scalar, affectedRows or none — and may carry
statement, field, nativeDataType and encoding. encoding is json or string and is
legal only on a scalar.
The Returns picker writes three of the four modes, into the active connection’s dialect rather
than the implementation. Affected row count is { mode: 'affectedRows' } and is also what an
absent result reads back as; Rows of the last statement is { mode: 'rows' } naming that
statement; Nothing is { mode: 'none' }. A result the picker cannot express — a scalar, or a
rows naming a statement that is not the last — reads back as a fourth, unselectable label,
Explicit result, and is preserved untouched. The picker is disabled while the layer’s connection
maps to none of the thirteen dialect names, because a write would then have nowhere to go.
A workflow’s parameters are an ordered array. Each requires name and dataType and may carry
description, reference, default, nullable and evaluation. An omitted default is not
the same as an explicit null, false or 0, because the check is for the property’s presence.
evaluation is accepted by both shape checks and by MCP, and read nowhere.
A binding holds exactly one of reference or value, plus optional dataType, nullable and
encoding, whose only accepted value here is json — unlike a result’s encoding, which also
takes string. A reference carries exactly one key: parameter, naming one of the workflow’s
declared parameters; context, an identity string; or input: 'rows', which is the only value that
key takes.
The trusted identity contexts the editor writes are user.email, user.id and user.name. The
Value picker lists them as Email, User ID and Name under a User attribute group,
beside Any value and Explicit binding; the closed control and the summary line spell the
three as User attribute: Email, User attribute: User ID and User attribute: Name, so the
menu and the summary do not read alike.
An identity source is selectable only where the declared type can hold one: a parameter typed as
text — varchar, nvarchar, char, nchar, character, character varying, string or text,
in any case and with or without a length — or uuid for User ID alone, and a writable-table
field whose layer type is exactly string. Elsewhere the three stay in the menu but cannot be
chosen, and the option reads Requires a text parameter, or a UUID with User ID. That rule lives in
the picker alone: a definition written in the Dev tab or through MCP can bind an identity to a
parameter of any type, and no issue reports it.
A reference’s dataType and nullable are for one context class. A context beginning customer.
must declare dataType, and is the only reference that may carry nullable, or override the native
type of a procedure argument; both are refused elsewhere as reference datatype/nullability overrides require customer context. A dataType on any other reference in a keys, values or
bindings map is accepted, because there is no native type there to override. Nothing in the editor
writes a customer. context; it is there for a document authored outside it.
A default on a parameter, and a value on a binding, may be a JSON scalar or an array of
scalars. A nested object or a non-finite number is refused as expected a JSON scalar or scalar array.
fields and returns describe a workflow rather than drive it. fields maps a field name to a
note holding description and reference, and nothing else — the editor’s Note and
Refers to pair. returns holds one required fields map, from an output name to a required
dataType and an optional nullable; it declares an output shape and is unrelated to
implementation.result, which chooses what a run hands back.
A reference on a parameter or a field note takes a different shape from a binding’s: exactly one of
{ parameter }, { dimension }, { measure }, { businessQuestion }, or the two-key
{ view, field }. The two keys spelled parameter resolve in different scopes. On a parameter
or a field note it names an SQL parameter declared on a view or a measure anywhere in the layer; on a
binding it must name one of the workflow’s own declared parameters.
dialects.<dialect>.arguments is ordered: position n binds the procedure’s nth argument. Each
entry is a binding plus a required nativeDataType. A value argument, and one bound to a
customer. context, must also declare dataType; a parameter or input reference must not,
because it inherits its type and nullability. MCP enforces the same two rules in its own words:
Literal and customer arguments require dataType. and
Parameter and input references inherit their type and nullability.
What publishing requires is in the validator rather than the schema, and differs by kind:
| Kind | Needed to publish |
|---|---|
table |
An implementation.view naming a mapped physical-table view, one operation, and keys bindings when that operation is update or delete. Every name in keys, values and fields must be a field of that view, and a fields note needs a key or value binding to sit on. |
storedProcedure |
At least one dialect entry, each carrying a procedure. Where an entry matches the connection’s own dialect, names a schema and that schema’s catalogue has been read, its procedure must appear there with the same argument count and the same ordered native types; a catalogue that cannot be read is reported in its place. |
virtualProcedure |
At least one dialect entry, each carrying at least one named statement. |
Three rules apply to every kind: a parameter declared twice, a binding naming a parameter the
workflow does not declare, and a reference pointing at an entity the layer no longer holds are each
reported against the workflow.
astrato_semantic_layer_apply_data_action_change takes one of five operations — create, replace,
update, rename and delete. An update carries a patch in which an omitted property keeps its
value and null clears optional metadata; implementation is the exception, replaced whole rather
than merged, and it cannot be cleared.
Copying a layer
Section titled “Copying a layer”MCP copying requires the data-actions feature; ordinary empty-layer creation remains available while it is disabled.
Copying an older layer keeps its valid stored filters, business questions, datasets, map layout and
authoring settings and skips invalid fields. If the source changes during the copy, or the new layer
is opened before the copy completes, the copy fails and cleanup is attempted. A copy that returns no
usable layer ID is reported as a failure; check the layer list before retrying. If an HTTP error
includes cleanupFailed: true and createdId, delete that incomplete layer before retrying. A
document import fails in the same way instead of dropping editor-owned content. MCP errors name the
layer when cleanup fails. Otherwise, retry to copy the current definition.
Model at a glance
Section titled “Model at a glance”flowchart LR connection[Data connection] -. routing context .-> layer[Semantic layer] layer --> views[Views] layer --> joins[Joins] layer --> dimensions[Dimensions] layer --> measures[Measures] layer --> udfs[Functions] layer --> questions[Business questions] layer --> storedFilters[Stored filters] views --> fields[Fields] views --> filters[View filters] joins --> views fields --> dimensions[Dimensions] fields --> measures[Measures] dimensions --> dimensions measures --> measures dimensions --> questions[Business questions] measures --> questions fields --> questions fields --> storedFilters storedFilters --> questions udfs[Functions] --> queries[Query expressions] acl[Access grants] -. protect .-> layerSolid arrows show containment or semantic references. Dotted arrows show platform context that is stored outside the V3 entity collections.
Entity inventory
Section titled “Entity inventory”| Entity | Identity and ownership | Important properties | References |
|---|---|---|---|
| Semantic layer | An external semanticLayerId identifies the resource. The ID is not embedded in V3. |
name, description, datasource, locale, queryFeatures |
Routes to one data connection through datasource. |
| View | Keyed by name under views. A view owns its fields, SQL parameters, and row filter. |
source, description, sqlAlias, singleGrain, filter, filterMode |
A source names a physical object, contains custom SQL, or contains inline data. |
| Field | Keyed by name under a non-inline view. Inline columns are the fields of their view and preserve array order. | source, dataType, optional native type, label, description, precision, enabled state |
Always belongs to one view. Other entities use { view, field } references. |
| Join | Ordered entry under joins; its two endpoints provide its semantic identity. |
views, cardinality, ordered conditions |
Connects exactly two views. Each condition compares expressions, normally fields from the endpoints. |
| Dimension | Keyed by name under dimensions. |
Common metadata plus the properties of its variant | A field or bucket dimension references a field. A drillthrough contains ordered field or dimension levels. |
| Measure | Keyed by name under measures. Its class is derived, not stored. |
resultType, formula expression, m1… operand blocks, format, parameters, metadata |
Operands may reference fields, measures, or measure-local parameters. |
| Function | Keyed by name under udfs. Function signature order is significant. |
kind, path, resultType, ordered parameters, supportsDistinct, metadata |
Query expressions bind arguments to signature parameters. Stored measures do not publish function calls in the current model. |
| Business question | Keyed by name under businessQuestions; top-level and independent of datasets. |
Meaning and business-value prose, selections, filters, sorting, chart recommendations, defaults | Selects fields or dimensions and measures; follow-ups reference other questions by name. |
| Dataset | Keyed by name under datasets. Editor-owned; it is not sent to the query engine. |
description, categories, ordered dimensions and measures, filters |
Lists existing dimensions and measures by reference. Filters are pre-aggregation conditions on fields or dimensions, as on a business question. |
| Stored filter | Keyed by name under filters, across both types. Editor-owned; it is not sent to the query engine. |
description, categories, and exactly one associativeFilters or filters body |
A set filter keeps target values; a regular filter holds conditions. Consumers use reference: { filter: name } in the matching existing slot. |
| Data action | Keyed by workflow name under dataActions. A draft contract, behind the data-actions feature. |
kind, implementation, and optional description, parameters, fields and returns |
A writable table names a view and its fields; a virtual procedure binds its own parameters. See Data action properties. |
Eight top-level properties are required: fileVersion, name, views, joins, dimensions,
measures, udfs and layout. Everything else is optional. The V3 document has no top-level
object, relationship, security-rule, or table-limit collection, and an unsupported top-level
property is rejected instead of being silently discarded.
Shared item metadata
Section titled “Shared item metadata”Dimensions, measures and functions share a metadata block: label, description, categories and
synonyms, the last an array of unique strings.
Synonyms are a live setting with no editor control. The MCP query catalogue matches a search against an item’s name, label, synonyms and description, and scores candidates by them — so a synonym is how someone’s own word for a measure finds it. Nothing in the editor authors them: the measure editor’s input is switched off, and the dimension panel’s editable list is wired to Categories. They reach a layer from a Snowflake or Databricks import, from MCP, or from a Dev tab or YAML document, and they survive an edit in the editor even though nothing shows them.
View and field variants
Section titled “View and field variants”A view has exactly one source variant:
| Source kind | Stored source | Field ownership |
|---|---|---|
| Physical table or view | type: table plus table, and optionally database, schema, and objectType |
The view’s name-keyed fields map describes physical or expression fields. |
| Custom SQL | type: sql, a statement, and optional typed parameter defaults |
Result fields are stored in the view’s fields map. |
| Inline data | type: inline, ordered columns, and header-bearing csv |
columns are the fields; an inline view does not have a second fields map. |
Physical source identifiers preserve the exact casing supplied by the data source. Source discovery metadata is temporary catalog context, not part of the semantic-layer document. Confirmed missing source objects can be marked on the affected view, field, or function so the draft remains repairable; see Semantic layer issues.
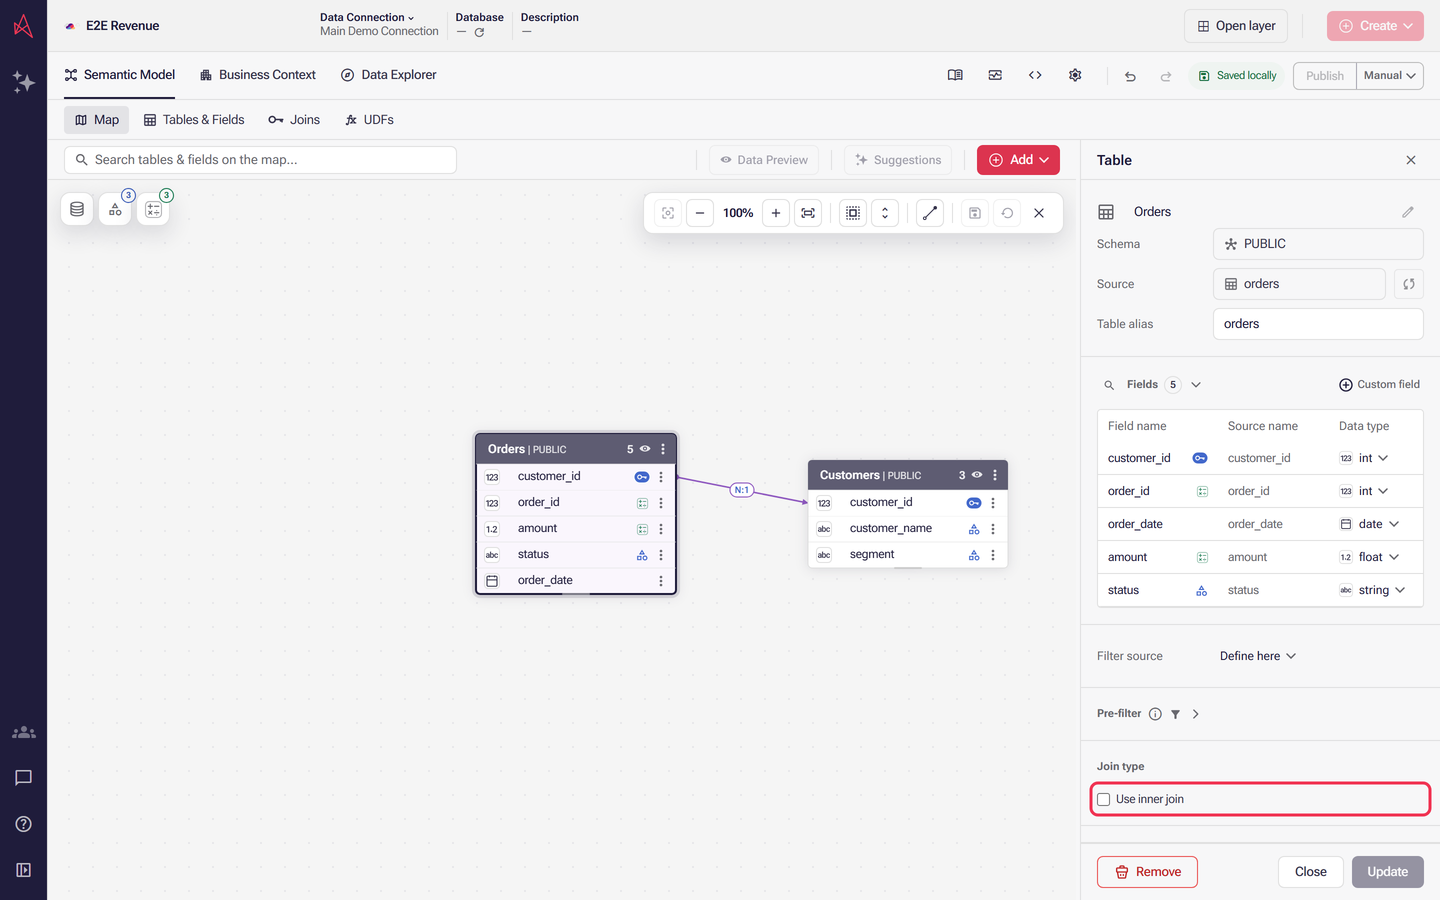
A view’s singleGrain accepts only auto. In the table panel, the Use inner join checkbox
under Join type sets it; clearing the checkbox removes the property. The section appears only
when Settings → General → Enable inner join for tables is on. Turning that off hides the
section and leaves any singleGrain already set in place.
Custom SQL int parameter defaults must be within the exact integer range
−9,007,199,254,740,991 to 9,007,199,254,740,991. Values outside that range are rejected
instead of rounded. Boolean defaults are stored as true or false and keep that representation
when you reopen and save them.
For a list parameter, use {ids:int_list} or {labels:string_list} in your Custom SQL
and enter a comma-separated default such as 1,2 or ok,other. Validate SQL checks
the statement using those defaults. After validation succeeds, Run SQL preview runs the
same statement with the same defaults and shows its first 20 records. Keep the list type
in the SQL token; you do not need to change it to int or string to validate or preview.
Field data types
Section titled “Field data types”A field’s dataType is the engine’s own enum, matched exactly and in lower case. Sixteen values
are accepted:
string, int, integer, float, number, decimal, date, time, time_tz, timestamp,
timestamp_tz, boolean, bool, json, geography, unhandled.
An inline view’s columns take a narrower nine: date, timestamp, timestamp_tz, string,
int, float, number, boolean and bool. Both checks print the whole accepted list in the
error, so the valid set is on screen at the point of failure:
source.columns[2].dataType: dataType "json" is not supported. Use one of: date, timestamp, ….
The accepted set is wider than the one the product offers. The type picker on a field row
offers eight — boolean, date, float, int, string, time, timestamp, timestamp_tz —
so a decimal or a json written in the Dev tab validates but cannot be reached through the
picker afterwards. It is shown rather than hidden, but decimal and bool have no display name of
their own, so a field carrying either shows no type icon and its raw value as its label.
A physical column may additionally opt into a driver’s native type, stored as nativeDataType
beside its dataType; the picker then displays the native name in place of the canonical one. The
pairing is checked against the connection’s driver, and one combination exists today: BigQuery’s
INT64, which pairs with dataType: string. Anything else is a validation error naming the native
types that driver accepts, or (none) where it accepts none. The check needs the layer’s
connection; a draft with no resolved connection does not report a bad pairing.
Two derived kinds narrow it further, and these two comparisons are case-insensitive:
- A bucket dimension’s source must be
int,integer,float,numberordecimal— “Select a numeric source field for the bucket dimension.” - A period axis source must be
date,timestamportimestamp_tz— “Select a date or timestamp source field for the period axis.”
A join key is checked the same way: two sides must carry either the same type or two numeric-family types.
An inline table authored in the editor offers six types, and timestamp_tz, number and bool
are not among them. Writing one by hand is accepted by validation here but may still be refused
further down: the CSV importer rejects timestamp_tz and bool, and takes json only to fail when
the row is written.
Dimension variants
Section titled “Dimension variants”Set a dimension’s optional label alongside its kind. The label controls its display text;
the dimension’s map key remains its identity for references. Publishing and importing preserve
the label across dimension variants.
| Kind | Meaning | Relationship |
|---|---|---|
field |
Reusable semantic name for one physical or calculated field | References one { view, field }. Date level, date part, and formatting are optional. |
bucket |
Evenly spaced numeric groups | References one field and owns a bucketing block of five required settings. |
mapping |
Custom groups evaluated in order; the first matching rule wins | References a base field and owns filters, typed group values, and an optional default. |
drillthrough |
Ordered hierarchy for moving from summary to detail | Contains one or more field or dimension references. Level order is semantic. |
periodAxis |
Reusable date window for period-aware calculations | Owns periodAxis.sources, period, and level. |
A drillthrough may reference ordinary field dimensions. Cycles and drillthrough-to-drillthrough nesting are invalid because the ordered field sequence must be deterministic.
A period axis uses the same block globally and inside a named business question. See Period axes reference for the full YAML contract, relative dates, multiple sources, compatibility rules and examples.
Bucket settings
Section titled “Bucket settings”A bucket dimension’s bucketing requires all five of minValue, maxValue, buckets,
bucketNo and outerBuckets — the first three finite numbers, the last two booleans. Miss two or
more and the error states the whole shape at once rather than one key at a time:
bucket dimension is missing `bucketing.bucketNo`, `bucketing.outerBuckets`. It needs resultType,reference: {view, field} and bucketing: {minValue, maxValue, buckets, bucketNo, outerBuckets}bucketNo decides what a row reads as — the bucket’s number when true, the value the bucket starts
at when false. outerBuckets decides whether values outside the range get buckets of their own or
fall out of the result.
A bucket excludes its maxValue. A row exactly at maxValue is outside the range, so with
outerBuckets false it reads as null. When the editor or MCP fills in the range from the field, the
maximum is the next whole number above the field’s highest value: a field measuring 1 to 100 gets 1
to 101. Set a range yourself with the same rule in mind.
Those two flags have three spellings. The document stores bucketNo and outerBuckets. MCP
authoring and the filter transform below call them includeBucketNumber and includeOuterBuckets,
and an MCP create defaults both to false when they are omitted, because the document requires
them. The MCP query catalogue reports them as enumerations rather than booleans: value is
bucketNumber or bucketStart, and outOfRange is outerBucket or null.
A bucket dimension’s authored resultType is ignored. The schema requires it, but the compiler
overwrites it from bucketNo on every load: int when true, float when false. Writing
resultType: int beside bucketNo: false does not make the dimension an integer; it makes the two
disagree until the next load silently settles it.
Validation adds two rules the shape check does not: the range must increase, and the count must be
a positive whole number. So buckets: 0 or buckets: 2.5 is a well-shaped document that fails to
publish, with “Enter an increasing bucket range and a positive whole-number bucket count.” The
editor’s Buckets box clamps what you type to at least 1 but does not round it, and MCP refuses a
count that is not a positive integer, so a zero count arrives only from the Dev tab or a YAML
import.
In the editor, Distribution holds Min value, Max value, Buckets and
Include out-of-range buckets; a new bucket dimension starts at 0 to 100 in 5 buckets with both
flags off. There is no control for bucketNo anywhere, so a bucket that reports numbers rather
than range starts can only be written in the Dev tab or imported.
A filter subject can carry the same banding as a transform, under different names:
transform: { bucket: { minimum, maximum, count, includeBucketNumber, includeOuterBuckets } }. You
rarely write it: the compiler derives it when it opens a legacy filter that carried its own
bucketing.
Custom-group values
Section titled “Custom-group values”Custom-group rules preserve empty text and null as distinct values. Equality with null checks for a missing value. A list containing null and text matches either, including an explicitly authored empty string. Exclusions follow ordinary filter behavior: excluding non-null values retains null rows; excluding only null matches non-null rows.
Integer group values and defaults use the same exact integer range as SQL parameter defaults. Out-of-range values remain available for correction in the editor and block publication.
Date and time comparisons carry their type with their text, for example
{ value: '2026-09-23', dataType: date }. Simple and advanced editing preserve that type.
Rules containing null comparisons or empty-string list members open in advanced mode so those
values remain distinguishable. Legacy millisecond literals cannot be compiled into custom-group
rules; replace them with explicit date or time text and its matching type. Validation reports
this before publication.
Date grouping
Section titled “Date grouping”Choose date grouping by the question you want to answer:
| Setting | Meaning | Across years |
|---|---|---|
dateLevel: month |
A date-valued monthly time bucket | January 2025 and January 2026 remain separate. |
datePart: month |
The numeric month of the year | Both Januaries share the same value, useful for seasonal comparisons. |
A chronological monthly trend can span years without changing its date level. Use date parts when you intend recurring calendar categories, rather than choosing them from the number of years in the data. Date grouping and period comparisons serve different purposes.
Measure variants
Section titled “Measure variants”Set a measure’s optional label alongside its expression and resultType. The label controls
its display text; the measure’s map key remains its identity for references. Publishing and
importing preserve the display label, including for derived, conditional and period measures.
measures: Order Count: label: Distinct orders resultType: int expression: '{m1}' m1: aggregate: COUNT distinct: true arguments: - reference: view: Orders field: Order IDEvery measure uses the same readable formula plus operand-block representation. Its compatibility class is derived from the formula and references:
| Derived class | Rule |
|---|---|
| Aggregate | Contains no named-measure reference. |
| Derived | References named aggregate measures and contains no conditional if expression. |
| Conditional | Contains an if expression and at least one named-measure reference. |
Measure formulas refer to sibling blocks such as {m1} and {m2}. Nested definitions may use qualified names such as {m2m1}; these names resolve only inside their own calculation. An operand can be a
reference, scalar or date value, operator, aggregate, or function call. Aggregate operand
keys below lists everything an aggregate may own.
Measure-local parameters are name-keyed typed defaults referenced from operands or aggregate
filters.
The aggregate’s fanout option is omitted by default. fanout: allow enables fanout;
fanout: reduceToRelation enables fanout with reduction to the relation’s dimensionality. Those
are the only two values; any other is refused as expected allow or reduceToRelation.
Publishing and YAML import preserve both parts of the reduced-fanout setting. Check results
at each intended grouping: a correct ungrouped total does not establish that results across
a many-to-many join are correct.
Structured comparison operators use textual names such as notEquals. Measure expression
strings use formula symbols: =, !=, >, >=, <, and <=. For example,
if({m1} != 'External Calculation', 'Not required', 'Required') compares the referenced measure
to a string. Each textual comparison has one formula spelling; notEquals renders as !=.
Legacy <> comparisons remain readable and normalize to != when rendered for execution.
Timestamp parameter defaults are independent of your device timezone. Use a full ISO date and time
with seconds and at most three fractional digits. A timestamp without an offset keeps its
wall-clock value; an explicit offset is normalized to UTC. A timestamp_tz must include Z or an
explicit UTC offset, for example 2026-01-02T03:04:05+13:00. The editor does not guess an offset from
the model timezone. Existing numeric defaults remain epoch milliseconds. Invalid calendar dates
and values finer than millisecond precision are rejected rather than silently changed.
The model’s locale.timezone accepts named IANA timezones such as Pacific/Auckland, including
supported aliases such as US/Pacific. Names are case-sensitive: US/pacific is invalid.
Timezone-aware timestamp grouping and relative date boundaries use the model timezone,
including its daylight-saving rules. Date-only and unzoned timestamp values retain their
own type-specific behavior.
When the entire locale is omitted, query compilation uses the engine’s Europe/London
default. If locale is present, set timezone to a string: use UTC or an empty string
for UTC, or a named zone. A missing timezone inside a present locale, invalid names,
standalone offsets and the machine-dependent Local value are reported as settings errors.
An existing invalid setting remains visible in a draft so you can repair it before publishing.
An aggregate measure can add a stored period comparison while keeping the same formula and operand blocks:
dimensions: Order Timeline: kind: periodAxis resultType: date periodAxis: sources: - reference: { view: Orders, field: Order Date } period: currentYear level: monthmeasures: Sales growth: resultType: float expression: '{m1}' m1: aggregate: SUM arguments: - reference: { view: Orders, field: Amount } periodAxis: reference: { dimension: Order Timeline } comparisonPeriod: year periodComparison: type: growth reference: { dimension: Order Timeline }Stored period comparisons accept current, value, diff, ratio, and growth. They reference a period-axis
dimension. An explicit comparison offset belongs to the measure-local periodAxis binding. Named periods can retain their built-in previous interval by omitting the offset; relative periods require an explicit offset.
Explicit reduction belongs to the sibling nestedCalculation property.
Aggregate operand keys
Section titled “Aggregate operand keys”An aggregate operand accepts seventeen keys and refuses any other by path. aggregate is a
required non-empty string and arguments a non-empty array; parameter is shared with every other
expression node and is how a measure-local parameter is attached.
| Key | Accepts |
|---|---|
distinct, absolute, cacheResult, geoMakePoint |
boolean |
scope |
total and nothing else |
filteredOutValue |
zero or null |
delimiter |
string |
geoSimplify, options |
object |
orderBy |
array of { reference, direction? } |
partitionBy |
array of { reference } |
withinGroup |
a single { reference, direction? } |
filter, fanout |
a filter block, and the fanout setting described above |
filteredOutValue: null is accepted by the shape check on any aggregate but by validation only on
a SUM: anything else reports “Use null in measure filter is supported only for SUM.”
orderBy, partitionBy and withinGroup reach the engine as the ORDER BY, PARTITION BY and
WITHIN GROUP clauses of a windowing function, and its contract states that a partitionBy omits
the GROUP BY the query would otherwise carry. An aggregate’s partitionBy is not the
partitionBy of a business question’s advanced calculation,
which names that question’s own dimension keys; see the
business question YAML reference for that one.
The measure panel and formula editor expose Total (scope: total), Abs
(absolute: true) and Fanout. Fanout has three modes:
| Mode | Document value | Behavior |
|---|---|---|
| Disabled | fanout omitted |
Uses the measure’s normal relationship rules. |
| Allow fanout | fanout: allow |
Allows joined rows to repeat before aggregation. |
| Allow fanout with relation reduction | fanout: reduceToRelation |
Reduces repeated joined rows at the relation’s dimensionality before aggregation. |
Count distinct and other supported distinct aggregations set distinct: true independently.
They aggregate unique values; relation reduction operates on the joined rows and their relation
keys. A measure can use both. Changing either setting preserves the other. Imported fanout modes
remain selected when you edit a measure, and version comparison shows fanout for each operand,
including embedded calculations. Row-expression aggregates offer the same fanout modes.
Use null in measure filter writes filteredOutValue: 'null'. The formula editor offers it on
single-field aggregates and disables it outside SUM; the measure panel disables it until there
is a filter. Validation requires SUM. Clearing an option removes its key.
delimiter, cacheResult, geoMakePoint, geoSimplify, withinGroup, partitionBy and
options have no control anywhere in the editor. They are not casualties of that: MCP preserves
them deliberately when it replaces an operand that aggregates the same thing, and they round-trip
from legacy layers. Five reach the engine verbatim; partitionBy and withinGroup are rewritten
into the engine’s own field-key shape on the way.
The options the editor does write are renamed for the engine, so an aggregate in the document and
the same aggregate in an engine request do not read alike: fanout: allow becomes allowFanOut: true,
fanout: reduceToRelation adds reduceToRelationDimensionality: true beside it, scope: total
becomes total: true, and filteredOutValue: 'null' becomes allowNullForSumFilters: true. Only
absolute keeps its name. options is spread last, after every one of them, so a key inside it
overrides whatever the aggregate derived.
A list aggregation gets a delimiter whether or not the document holds one: LISTAGG,
LISTAGG_DISTINCT, VALUE_LIST and VALUE_LIST_DISTINCT fall back to a comma and a space.
Every one of the option keys above except distinct makes a measure too complex for
Apache Ossie export. A Databricks metric-view export is blocked by the same set
apart from filter and cacheResult, so a measure whose only option is one of those two exports
to Databricks and not to Ossie.
Filters, table limits, and row-level security
Section titled “Filters, table limits, and row-level security”A filter is embedded where it applies, unless it is stored under filters as a named entity for
questions to reuse. It stores a Boolean formula over sibling condition blocks such as
{f1} AND ({f2} OR {f3}). Each condition owns an operator and ordered expression arguments.
| Owner | Effect |
|---|---|
View filter |
Restricts rows before queries use the view. filterMode controls whether the filter is active and strict. |
Aggregate operand filter |
Restricts rows used by that aggregate. |
Business-question filters |
Applies before aggregation. Subjects may be fields or dimensions. |
Business-question resultFilters |
Applies after aggregation, before or after advanced calculations depending on its subject (details); with keyed measures it addresses completed selection keys. |
Stored regular filter |
Reusable conditions, referenced from a compatible regular filter slot; the consuming slot determines when they apply. |
Table limits and row-level security are authoring views over a view’s existing filter and
filterMode; they do not create another collection. A view-filter comparison against the reserved
user-context parameters $userEmail or $userGroupNames is resolved per requesting user. Other
view-filter comparisons are ordinary static pre-filters.
When opening legacy layers or drafts saved by an older importer, view and aggregate filters
recognize untyped strings as dates only when the comparison expects a date and the value is a
real calendar date in exact YYYY-MM-DD form, such as 2026-08-14. The text stays unchanged;
the literal gains dataType: date. This does not infer timestamps or numeric date parts, change
explicit types, or repair invalid dates. Values outside this rule keep their existing validation
diagnostics so you can correct them before publishing. New document authoring still requires
explicit date types.
filterMode, and where the group limit lives
Section titled “filterMode, and where the group limit lives”filterMode is an object of exactly two required booleans, active and strict. The editor always
writes both: a filter with no stored mode is treated as { active: false, strict: false }.
Apply as global data reduction writes active. Strict writes strict, and its checkbox is
rendered only while active is true. Ticking Apply as global data reduction sets both to true,
and clearing it sets both to false; a document written another way can still carry strict: true
with active: false and show no control for it. What strict changes is decided by the query engine; nothing on this
side defines it. The engine’s published contract declares both booleans with a default of true,
while this side treats an absent mode as { active: false, strict: false }, so the two disagree
about an unwritten value. Write both rather than relying on either default.
Only a physical-table view offers the controls, and the engine agrees: its own filter-group-config
rule refuses an active mode on a statement view, and refuses one with no conditions.
Removing the last condition keeps the mode. Dropping a view filter’s conditions removes
filter and leaves filterMode in place, so a view can carry a mode with nothing to apply. Only
the section’s Clear removes both.
Limit to groups is not a property of its own. The list is stored as the view filter’s
userGroupNames SQL-parameter default — one comma-separated string — which is why a group name
cannot contain a comma, and why the editor refuses one with “Group names cannot contain a comma.”
On compile it is split on commas, trimmed, emptied entries dropped, and sent to the engine beside
the mode. The limit is sent whether or not the rule is a global data reduction; with no limit at
all, the view’s filterMode is sent verbatim, or nothing is sent when the view has no mode.
Both directions join the names with a comma and a space: the editor writes A, B, and reading an
engine model back writes the groups it carries to the same parameter default in that form. Compiling
re-splits and trims, so A,B and A, B are the same limit.
Two user-context parameter names are reserved, userEmail and userGroupNames, and the literals
$userEmail and $userGroupNames are what resolve per requesting user. $userGroupNames holds
several values, so a condition comparing against it takes only inList or notInList; pointing an
existing condition at it rewrites the operator to one of those.
MCP authors the mode directly: astrato_semantic_layer_apply_view_change takes filterMode as a
strict object of those two booleans, and null clears it.
For the task rather than the shape, see Restrict rows with a security rule.
Access control is outside the document
Section titled “Access control is outside the document”Semantic-layer access grants protect the whole semantic-layer resource and are not V3 entities. See Manage resource access for granting permissions to people, groups, workspace roles or everyone in your workspace. With explicit resource access enabled, creating a layer does not provide irrevocable access: the creator’s grants can be changed or removed. Workspace owners and administrators retain full access. Row-level security controls which source rows a permitted query can return.
Keeping access grants outside the V3 document prevents copying or exporting semantic definitions from accidentally copying resource permissions.
Business questions are terminal consumers
Section titled “Business questions are terminal consumers”A business question combines governed selections with the prose needed to understand the answer.
Its dimension selections may reference fields directly or reference named dimensions; its measure
selections reference named measures. Selections are ordered lists, and list order is the
presentation order. Give every entry a key when you need local aliases, inline periodAxis
dimensions, or local calculations; keys then identify the question’s output columns, and advanced
calculations refer to the dimension keys. Filters, result
filters, prioritized sorting, Top N, chart recommendations, categories, and follow-up questions
refine how consumers use it.
Questions are stored and versioned with the semantic layer but are not emitted to the query engine’s legacy composite. They are still validated: a missing selected entity or a question with no measure blocks publication because an agent could not execute it. Renderer recommendations are advisory; omitting output configuration means table output. See Business questions.
Model locale
Section titled “Model locale”locale is optional, but it is all-or-nothing: a present locale must carry number, formats
and calendar beside its timezone. Omit one and compilation stops with
$.locale.number: expected an object, naming whichever sibling is missing.
| Key | Shape |
|---|---|
locale.number |
decimalSep and thousandSep, both strings |
locale.formats |
date, datetime, money, number, numberInt and time, all Excel format patterns |
locale.calendar |
dayNames and dayNamesAbbr (7 each), monthNames and monthNamesAbbr (12 each) |
locale.timezone |
An IANA name, or an empty string for UTC |
A missing key inside one of those objects is reported against locale, not against the key.
A formats block without date fails with $.locale: locale property `date` must be a string,
so searching the error for $.locale.formats.date finds nothing. Only a wholly absent sibling
object is reported at its own path.
Calendar lengths are enforced twice over, by the published v3 schema and again by validation, which
reports locale.calendar.dayNames must contain exactly 7 entries, got 3. An empty or whitespace-only
entry is its own error: locale.calendar.monthNames[4] must be a non-empty name.
Format patterns
Section titled “Format patterns”A pattern is an Excel format pattern, not a formula. The editor refuses eight ways: a leading =
or any brace, a control character, an empty box, more than 128 characters, more than four
semicolon-separated sections, unbalanced brackets, unbalanced quotes, and a pattern carrying no
placeholder at all. The placeholder test looks for 0 # ? @ y m d h s in either case — YYYY-MM-DD
passes — and ignores anything inside double quotes or square brackets, so a d in a quoted literal
does not count as one.
When the layer defines no pattern, these are used:
| Format | Default |
|---|---|
date |
yyyy-mm-dd |
datetime |
yyyy-mm-dd hh:mm:ss |
time |
hh:mm:ss |
money |
$#,###.00 |
number |
#,##0.00 |
numberInt |
#,##0 |
A stored pattern that fails validation is read back as the default, not used. The invalid text
stays in the document — the Dev tab and the compare panel both show it, under
Locale › Formats › Date — but nothing formats with it. Five legacy sample values are discarded
the same way, in favour of the default: 2021-06-21, 2021-06-21 00:00:00, $2,500.00, 2,500
and 00:00:00.
Timezone
Section titled “Timezone”An empty string means UTC. A named zone must be an exact IANA name, so US/pacific is refused with
locale.timezone must be a named IANA timezone, such as Pacific/Auckland, or empty for UTC. That
is both a compile error and a validation issue, so it also appears in Issues and blocks
publishing. In the editor the control is a searchable picker rather than a text box, so an
invalid name usually arrives from a YAML import or the Dev tab.
What the editor writes
Section titled “What the editor writes”Settings → Format holds Decimal separator, Thousand separator, Date, Date time, Time, Number, Integer and Money; Locale holds Timezone. There is no control for the calendar names: the editor supplies English Gregorian defaults — Sunday to Saturday, Sun to Sat, January to December, Jan to Dec — and only the Dev tab or a YAML import can change them.
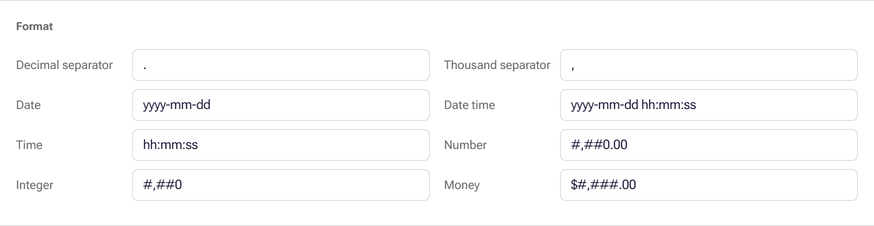
The two separators commit on every keystroke. The six pattern boxes beside them commit when the box loses focus, and only if the pattern passes the check, so a rejected pattern stays on screen with its reason and never enters the document.
Opening Settings and touching one field writes the whole locale. Every patch is merged over a
complete default first, so the editor cannot produce a partial one. The side effect is worth
knowing: a layer with no locale at all compiles at the engine’s Europe/London default, while
Settings → Locale → Timezone shows UTC, because the panel is displaying a default the
document does not contain. Edit any Format field and that UTC is written in, moving the
layer’s timezone without your having touched it.
Whatever locale holds reaches the query engine unchanged, so separators, patterns and calendar
names are live model settings rather than editor decoration.
Settings and derived state
Section titled “Settings and derived state”The following are document settings or derived state, not independently addressable semantic entities:
locale,queryFeatures,authoring,metadataand opaque engine compatibility properties apply to the document;layoutstores editor positions and display choices;- SQL and filter parameters belong to their owning view, measure, or filter;
- revisions, publication state, validation issues, source-catalog data, and query capabilities are computed or stored outside the V3 document.
The Dev tab exposes lossless V3 JSON and YAML. Apache Ossie export is a read-only projection of the current valid draft, not another authoring model.
Large YAML imports retain change history for every changed entity. Saving the imported draft is atomic: if saving fails, the previous saved draft remains intact. Creating a version also retains the complete change history for the revisions it covers.
authoring, queryFeatures and metadata
Section titled “authoring, queryFeatures and metadata”authoring holds two properties. enableInnerJoinForTables is a boolean written by Settings →
General → Enable inner join for tables, off by default; it decides whether table panels show
the Join type section, and turning it off changes no table’s join. groupedDimensionOptions
takes only dimensions and dimensionsOnly. Those are the two states of the Settings checkboxes: Show dimensions as
options writes dimensions, Show only dimensions switches it to dimensionsOnly, and
clearing the first drops both. It is a live setting — the custom-group Base field picker reads
it to decide whether to list dimensions and whether to hide table fields.

queryFeatures holds exactly three properties:
autoAssociativeFilters— Settings → General → Enable auto associative filters, a boolean that defaults to on. Anything other than an explicitfalseis treated as enabled, and only an explicitfalsereaches the engine, asdisableAutoAssociativeFilters. See Automatic associative filters for what it does.tableAliasInSqlInsights— Use table alias in SQL query insights in the same section, a boolean that is off unless explicitlytrue.options— an opaque object passed to the engine verbatim, an escape hatch for engine properties rather than an Astrato setting. It is spread beneath the derived associative-filter flag, sodisableAutoAssociativeFiltersis the one key inside it that the checkbox overrides.
Importing from the earlier engine format rebuilds autoAssociativeFilters and options and not
tableAliasInSqlInsights, while the aliases themselves are carried over — so a layer that came back
that way keeps its sqlAlias values and loses the setting that generated them.
metadata holds one property, importSources, keyed by DATABASE.SCHEMA.NAME. Each entry
requires format — snowflake-semantic-view or databricks-metric-view — plus datasourceId,
database, schema and name. It is the only top-level collection the schema marks editor-only
and never emits to the engine, and it is read widely: the imported-view icon and tooltip on a
table, the import callout on an element, the upstream-schema status, and the issue text when a
source has drifted all come from it. It is also the one setting collection version compare does not
read, so a changed import source produces no comparison row.
Table aliases are a model change, not a display preference
Section titled “Table aliases are a model change, not a display preference”Use table alias in SQL query insights, in Settings → General, presents itself as a
readability setting — its own hint says aliasing “improves the readability of the queries produced
by Astrato, and simplifies debugging and sharing the queries”. It does more than that. Turning it
on gives every view a unique sqlAlias, those aliases are serialized into the published engine
model, and the next draft save persists them. A reader who ticks it expecting a debugging
convenience has edited the model.
While it is on, each table’s panel gains a Table alias box with the placeholder “Generated from
the table name”. A typed alias is 3 to 8 characters of lower-case letters, digits and underscores,
starting with three letters and not ending in an underscore. Anything else is refused with “Use 3
to 8 characters: letters, digits and underscores, starting with three letters.”, which does not
mention the casing, so Orders is rejected without saying why; a clash reads
“Already used by table.” A refused alias is never stored: the box keeps the text while the table
keeps its previous alias.
Clearing the box hands the alias back to be generated again. Generation keeps an alias that already meets the rule, so your own naming survives; where two tables hold the same one, the first keeps it and the second is generated afresh.
Join comparison operators
Section titled “Join comparison operators”New and updated joins store these canonical textual values:
| Stored value | Editor symbol | Accepted V3 compatibility aliases |
|---|---|---|
equals |
= |
equal, =, == |
notEquals |
≠ |
notEqual, !=, <>, ≠ |
greaterThan |
> |
> |
greaterThanOrEqual |
≥ |
greaterThanOrEqualTo, >=, ≥ |
lessThan |
< |
< |
lessThanOrEqual |
≤ |
lessThanOrEqualTo, <=, ≤ |
Loading normalizes a compatibility alias to its canonical value. Applying or exporting the document writes the canonical textual operator. Unsupported values are rejected with the affected condition path.
Rename and removal behavior
Section titled “Rename and removal behavior”Names are entity identity in V3. Reference-aware rename operations can update supported dependent references atomically. Field data-type changes list definitions that read the field so you can review their compatibility before applying the change.
The editor asks for confirmation before removing a view, field, measure, dimension, join, or function. This includes entities with no known dependencies inside the semantic-layer document because a connected workbook can still use them. When dependencies are known, the confirmation lists the affected entities and lets you either remove dependent definitions or preserve them for manual repair. Preserved broken references remain visible as draft issues and block publication until repaired.
Removal confirmations block interaction with the editor until you confirm or cancel, so changing the current selection cannot retarget an open destructive action.
Measure selectors and explicit nested aggregation
Section titled “Measure selectors and explicit nested aggregation”Use periodAxis: { reference: { dimension: Order Timeline }, period: yearToDate, level: month }
for measure-local overrides. Use nestedCalculation: { aggregate: SUM, dimensions: [{ reference: { dimension: Order Timeline } }] } for an explicit reduction. An optional inner
nestedCalculation.periodAxis preserves its own settings separately from the outer binding.
See Measure overrides and reduction for full examples and editor instructions.
Calculations inside calculations
Section titled “Calculations inside calculations”A measure operand can contain a complete calculation definition. Use this to calculate a
result per City, reduce it with SUM or AVG, and compare the reduced results without creating
helper measures. Agent measure authoring writes this shape. In the measure editor, a measure
operand’s Nested calculation icon (Σ) writes its one-measure form, shown as a measure row with
its grain. A measure that already holds any other embedded calculation shows it in a calculation
form, so it stays editable and saves intact.
resultType: floatexpression: '{m1}'m1: calculation: resultType: float expression: 'if({m1m1} > 20000, {m1m1}, 0)' m1m1: aggregate: SUM arguments: [{ reference: { view: Sales, field: Amount } }] nestedCalculation: aggregate: AVG dimensions: [{ reference: { dimension: City } }]Here City is an existing stored dimension. The calculation first sums Amount per City, evaluates the IF for each City, then averages those results. At Country query grain, each Country gets its own average. Change the outer aggregate to SUM to sum those results.
New nested operands receive readable names such as m1m1. Existing m1 names remain valid
and are preserved when editing. Names do not navigate into other calculations. Each
calculation owns its parameters. Reductions support one ordinary stored dimension, or the
existing Time Axis settings, and require Business Questions to be enabled.
Within one IF, local aggregates cannot be mixed with embedded calculations or stored-measure references. Wrap each local aggregate in a calculation, or save it as a measure and reference it. To nest reductions, put the inner reduction inside a calculation operand. Import rejects the engine’s unsupported direct reduction-within-reduction shape.
This extends fileVersion: 3; older readers may reject it.
A layer that contains data actions does not support embedded calculations or qualified operand names. Validation reports this combination as an error.
What next
Section titled “What next”- Business question YAML reference — the contract for the stored questions this model contains.
- Working in the Semantic Layer Editor — where the document is edited, and how edits are saved.
- Publish your changes — an edit to the document reaches readers only once the layer is published.