

Astrato Query Metadata for telemetry - writing back the data
Overview: What We Do
Section titled “Overview: What We Do”To provide complete transparency and observability into your data warehouse workloads, Astrato automatically appends contextual metadata to every SQL query it executes. This metadata is injected as a JSON-formatted SQL comment at the very beginning of the query text.
By passing this application-level context down to your database, data engineers and database administrators can easily correlate warehouse activity, compute costs, and performance metrics directly back to specific Astrato users, workbooks, and scheduled reports.
How We Do It
Section titled “How We Do It”Whenever a user interacts with an Astrato workbook, generates a report, or triggers a query, Astrato constructs the SQL statement and prepends a -- comment containing a JSON object.
Because this is passed as part of the standard query text, it is automatically captured by your data warehouse’s native query history logs. You can then use your database’s built-in string manipulation and JSON parsing functions to extract these fields for analysis.
Example Query Comment, appended to queries
--{ "type": "query", "dimensions": [ "Product Manager", "Customer" ], "measures": [ "#Tickets" ], "fields": [ "Creator" ], "userId": "201526aa-c0d6-4d6e-a62d-9417d4eef153", "roleType": "administrator", "objectId": "1bde66c5-38d4-41d4-81c3-519691584312", "sheetId": "e4035568-90bd-44a6-a5e9-4288f8d4c11a", "workbookId": "a7dbf458-a008-4b83-9d75-84d566f8343f", "workbookState": "published"}[1] Setup script - creating the tables
Section titled “[1] Setup script - creating the tables”This is a script that customers can use to create the tables to store ASTRATO METADATA.
Please replace AUTO_TEST with a DB name.
create or replace schema AUTO_TEST.ASTRATO_METADATA;create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_COLLECTIONS ( ID VARCHAR(36), COLLECTIONNAME VARCHAR(999), WORKBOOKNAME VARCHAR(999), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_GROUPS ( GROUPID VARCHAR(36), GROUPNAME VARCHAR(255), USERID VARCHAR(36), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_SEMANTIC_LAYERS ( ID VARCHAR(36), NAME VARCHAR(255), DATACONNECTION VARCHAR(255), DATACONNECTIONID VARCHAR(36), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_USERS ( ID VARCHAR(36), EMAIL VARCHAR(255), NAME VARCHAR(255), FIRSTNAME VARCHAR(255), LASTNAME VARCHAR(255), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_USERS_PER_COLLECTION ( COLLECTIONID VARCHAR(36), ID VARCHAR(36), NAME_OR_EMAIL VARCHAR(255), USERACCESSACL VARCHAR(255), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_USERS_PER_SEMANTIC_LAYER ( SEMANTICLAYERID VARCHAR(36), ID VARCHAR(36), NAME_OR_EMAIL VARCHAR(255), USERACCESSACL VARCHAR(255), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_WORKBOOKS ( ID VARCHAR(36), NAME VARCHAR(255), DESCRIPTION VARCHAR(999), SEMANTICLAYERID VARCHAR(36), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_WORKBOOK_OBJECTS ( OBJECTNAME VARCHAR(255), OBJECTID VARCHAR(36), SHEETID VARCHAR(36), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());create or replace TABLE AUTO_TEST.ASTRATO_METADATA.ASTRATO_METADATA_WORKBOOK_SHEETS ( ID VARCHAR(36), SHEETNAME VARCHAR(255), WORKBOOKNAME VARCHAR(255), EXPORTED_AT TIMESTAMP_NTZ(9) DEFAULT CURRENT_TIMESTAMP());
[2] Creating the semantic layer
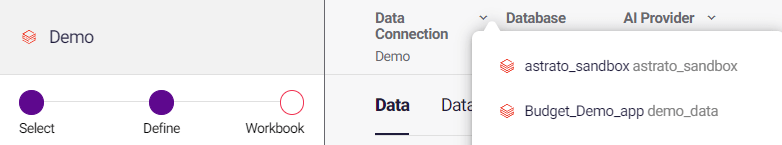
Section titled “[2] Creating the semantic layer”A semantic layer must be created first, this can be done by:
-
Editing the chosen semantic layer, and connecting it to a data source that can read and write to the
ASTRATO_METADATAschema setup before.
Metadata Field Reference
Section titled “Metadata Field Reference”The injected JSON object contains a variety of fields depending on the action being performed in Astrato. Below is the complete list of available metadata fields:
Field | Type | Description |
| String | The type of query being executed (e.g., |
| Array of Strings | The specific dimension columns queried in the visualization. |
| Array of Strings | The specific measure/metric columns calculated in the query. |
| Array of Strings | Any additional fields involved in the query (e.g., used for filtering). |
| UUID | The unique identifier of the Astrato user who triggered the query. |
| String | The Astrato role of the user (e.g., |
| UUID | The unique identifier of the specific visualization/chart widget. |
| UUID | The unique identifier of the sheet containing the visualization. |
| UUID | The unique identifier of the Astrato workbook. |
| String | The state of the workbook at execution time (e.g., |
| String | (Reports only) The name of the scheduled or exported report. |
| UUID | (Reports only) The unique identifier for the specific report execution instance. |
| String | (Reports only) The trigger type of the report (e.g., |
| String | (Reports only) How the report is being delivered (e.g., |
Key Use Cases
Section titled “Key Use Cases”By extracting this JSON metadata from your database’s query history, you can unlock advanced administrative capabilities:
-
Performance Monitoring & Tuning: Identify bottlenecks by correlating Astrato objects with warehouse execution metrics. Spot concurrency queuing caused by scheduled reporting (
reportRunType), or pinpoint specific user interactions (objectId,workbookId) that generate massive queries resulting in long execution times or disk spilling. -
Cost Attribution & Chargeback: Parse the
workbookId,userId, orreportNameto attribute warehouse compute costs to specific business units, departments, or individual users. -
Usage Analytics & Governance: Track which
dimensionsandmeasuresare queried most frequently to prioritize data engineering efforts, or identify published workbooks that haven’t generated queries recently so they can be deprecated. -
Troubleshooting: When a user reports a slow dashboard, admins can search the query history logs for the specific
workbookIdoruserIdto immediately find and analyze the exact SQL statements generated.
Extracting Metadata by Database
Section titled “Extracting Metadata by Database”Because the metadata is passed as a standard SQL comment, extraction methods vary slightly depending on your specific data warehouse’s SQL dialect and system tables.
You can extract this metadata from these data warehouses (a guide is available for Databricks):
-
Snowflake
-
ClickHouse
-
Google BigQuery
-
Postgres / Supabase